Thinking back to that incident, my OneUp auto-posting pipeline repeatedly sent the same post at two in the morning. When I picked up my phone and saw the notifications, I spent the next forty minutes manually deleting posts.
The lesson I took from that incident was that building a prototype that runs and making it work reliably within defined boundaries are two different jobs.
At the time, I had worked on three systems: a debate engine in which GPT-4o, Gemini, and Grok debate before Perplexity checks the result; a OneUp pipeline that reads a schedule from Google Sheets, generates images with DALL-E, and publishes to eight platforms; and another system used for production-line monitoring. Those were the configurations at the time, and each taught me something different. Including a checking step did not mean that every output was already correct.
This isn’t theory. These are five principles pulled from my mistakes.
Answer Three Questions Before You Write Anything
Before I touch a line of code now, I force myself to answer three questions: What problem is this Agent solving? What is it allowed to do? How will I know when it’s done something right?
They sound obvious. But the first version of my debate engine ran into trouble because I had not thought through the second question. I let the model decide freely how many rounds of debate to run. One session went twenty-seven rounds and burned through my API quota. I later added a hard limit of five rounds and forced the process to close after that. The cap limits the number of rounds; it does not prove that the models reached a genuine consensus or a correct conclusion.
Unclear boundaries make an Agent harder to accept or stop. Define its permitted actions, resource budgets, and stopping conditions before implementation begins.
Evaluate a Suitable API Before Choosing the Tool Interface
When an Agent calls tools to complete a multi-step task, each additional tool usually adds permissions, states, and failure modes that need to be handled.
I initially used browser automation to schedule posts, and UI changes often interrupted the workflow. I later switched to an API. My principle is to first assess whether there is a suitable, documented API with clear authorization boundaries. If it cannot perform the necessary work, I then consider browser automation. Both approaches need response checks, interface-change handling, and stopping conditions; the interface name alone does not guarantee stability.
The same applies to data. Missing input or an unexpected format can affect later judgments. Breaking Through the AI Storm discusses how I think about dividing work in collaboration. In Agent planning, I begin by checking the source, format, and permitted scope of the data.
Break It Into Modules So You Can Find What Broke
I use four modules: input processing, decision logic, tool calls, and result post-processing, and I try to make each part testable on its own. When a workflow has already published content or changed external data, it also needs separate stopping, reconciliation, and remediation procedures. Dividing a system into modules does not mean that an external effect can be rolled back.
That is how the debate engine is structured. The Input module parses the topic and mode (dialogue, duo, or adversarial). The Decision module controls round count and convergence. The Tool Calls module handles API requests to four models. The Post-processing module saves results as Markdown. This makes problems easier to locate and their impact easier to narrow, but shared state or incorrect data can still cross module boundaries.
This mirrors a principle I keep in my working notes: complex engineering must be broken into phases, each phase independently verifiable. Trying to handle everything at once usually means getting stuck midway and dragging down the parts that were already working.
Make Every Step Traceable—and Make Retries Safe
An Agent’s operation needs to be visible; otherwise, when something goes wrong, it is difficult to locate the failure.
The repeated posts made me notice that a timeout only means a response did not arrive in time. It does not prove that the external operation failed. Logs can help reconstruct events, but sending the same job again can still create a duplicate. AWS’s Making retries safe with idempotent APIs describes this problem as well. My planning advice is to give each job a unique identifier, record submission state, and query or reconcile the result before retrying. If an API supports idempotency keys, a retry should reuse the same key. If the effect cannot be established, automatic resubmission should stop.
I organize monitoring through three kinds of records: operation logs, recorded reasons for choices, and cost tracking. A reason generated by a model is not a complete record of its internal reasoning, and whether an operation succeeded still needs to be checked against the actual result. Access and content also need controls so that credentials or unnecessary sensitive data do not enter the logs.
Start With the Smallest Scenario
The last principle is the simplest and the most ignored: start small.
At the time, the monitoring system began by watching one parameter on one production line and expanded gradually after a two-week trial. The duration of that trial did not itself prove that full-line deployment or automated adjustments were safe. When You Hesitate to Begin: Clarify Risks and the Next Step discusses small attempts whose consequences are manageable and reversible. An Agent can likewise begin with a low-risk, stoppable, observable POC to gather feedback. Formal delivery, real data, and physical operations still require their own authorization and validation.
I want Agents to extend what people can do, not hide responsibility for the result. Scope, tool choice, modularity, traceability, and small-scale validation are five reminders I drew from failures. Each still needs to be checked against the specific task and its external effects.
Connecting Understanding to Its Consequences
An Agent that can run still needs boundaries that make it testable and stoppable.
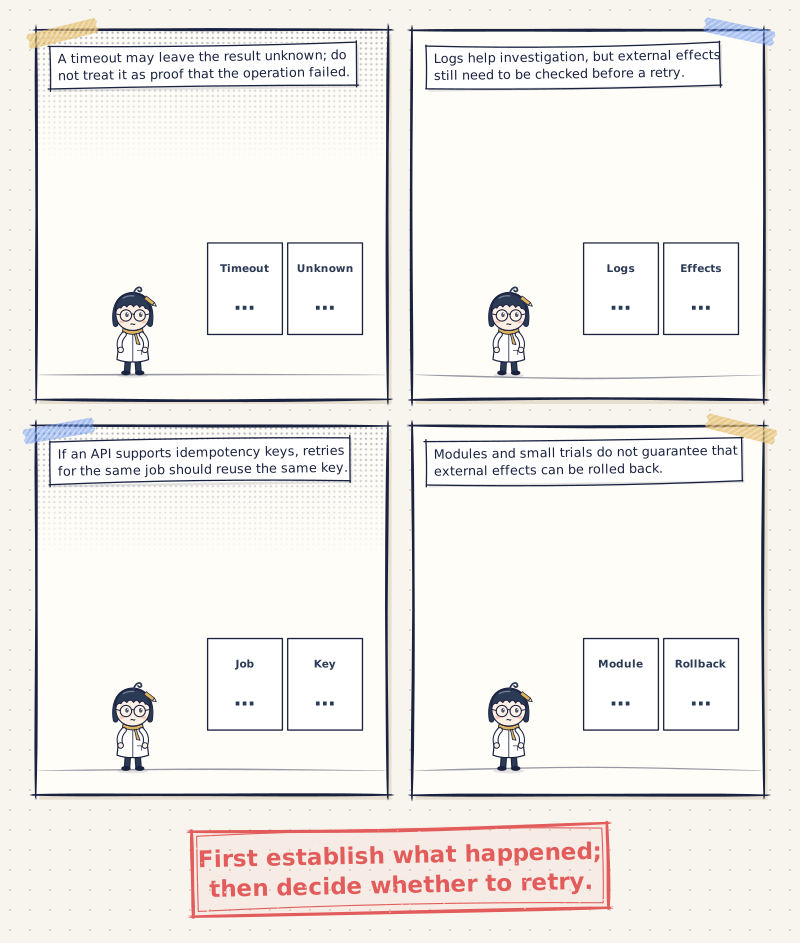
A timeout may leave the result unknown; do not treat it as proof that the operation failed.
Logs help investigation, but external effects still need to be checked before a retry.
If an API supports idempotency keys, retries for the same job should reuse the same key.
Modules and small trials do not guarantee that external effects can be rolled back.
First establish what happened; then decide whether to retry.
Revised November 5, 2026. The systems and incident describe my work at that time; the safe-retry principles draw on the linked AWS engineering article. The five principles are planning advice, not a claim that a particular service supports every mechanism or that a trial has established safety.

💬 Comments
Loading...