
TL;DR: Anthropic’s routines opened 388 PRs over a few weeks, with 180 merged. The shift is that agents initiated the work. In my August 14, 2026 account, I described 150 days of running similar processes and 23 launchd jobs. What concerned me was whether a running routine had actually achieved its result. Execution can be automated; the same system should not be the sole authority setting its acceptance standard.
On August 9th, I pushed a batch of commits to a mirror. The pre-push git health check crashed three times in a row, printing the words “no divergence.”
The origin for that same push was actually three commits behind, one of them a security fix.
The health check had not lied. It simply crashed before the detection finished, then reported a conclusion it had never verified, using the exact string I had hardcoded.
I changed that line to read “divergence state unknown (detection did not complete)” and left a note for my future self: this wording must never revert to “no divergence.” Once the health check crashes, divergence is unknown, not ruled out.
Five days later I saw Boris Cherny’s thread.
388 PRs over a few weeks: what does that mean?
Boris Cherny is the creator and lead of Claude Code. According to the thread screenshots saved in this article, he described how the team opened a Slack channel called proj-claude-maintains-apps and had Claude run a fixed set of maintenance routines there every day, spanning iOS, Android, Desktop, web, CLI, and the Agent SDK:
- Crash fuzzer: operates the app in a simulator, actively hunts for crashes, traces root causes, opens fix PRs
- Dup unifier: scans the codebase for functionally similar but diverging implementations and opens PRs to consolidate them
- Dead-code remover: deletes provably unreachable code; adds logging to uncertain cases, then checks actual execution the next day before deciding
- Logic simplifier / bugfixer: simplifies complex business logic and builds models to find logical gaps
- Flaky-test fixer: traces root causes of unstable CI tests
- Useless-test pruner: removes tests that can never fail
- Abstraction improver / police: addresses over-engineered abstractions and architectural layer violations


Source: Boris Cherny (@boris_cherny) on Threads
Over several weeks, these routines opened 388 PRs against their repos. After Claude Code Review plus human review, 180 were merged.


Source: Boris Cherny (@boris_cherny) on Threads
Reading the thread, I was not thinking about how much better Claude’s coding has gotten. What struck me was that the initiating role changed hands.
The old flow: a person spots a problem, issues a command, AI writes code. The new flow: a person defines rules and governance boundaries; an agent monitors the system continuously, finds problems, makes changes, runs tests, opens PRs, reviews, learns, runs again the next day.
The heaviest sentence in Boris’s thread, for me, comes in the third post: when something doesn’t go right the first time, they modify the routine so Claude does it better the next day, and sometimes it takes a few days to dial in. That means what the company is accumulating is no longer just code. It is operational knowledge: how this company maintains software.
The previous phase encoded engineering experience as SOPs, coding guidelines, and CI/CD pipelines. The next phase encodes that experience as a group of agent routines that clock in every day.
In the classic Copilot pattern, a person initiates the work and AI assists alongside. In this pattern, the agent takes on daily execution and the person steps back to handle governance, review, and exceptions. Boris told Fortune in June that he had not written code by hand in eight months, and that on some days he was managing hundreds, thousands, or even tens of thousands of agents simultaneously. At that scale, watching individual maintenance routines one by one is simply not possible.
How Many Automated Jobs Does It Take to Keep One Website Standing?
That thread resonated because I had been doing something similar on a much smaller scale. The figures below are the historical state described in the August 14, 2026 article, not a new inventory. At the time, I wrote that I had been doing it for 150 days.
At the time, launchctl list on this Mac showed 23 jobs I owned. A few examples:
- Daily 09:00: contract test. Reads roughly 116 endpoint contracts from
auth-contract.json, curls each one, checks the status, compares against the expected value. All green: sends a heartbeat to BetterStack. Any failure: exits 1 and appends the problem to a to-do file. - Daily 10:00: governance scanner. Checks recent commits for changes to shared files that are missing an impact-scope annotation.
- Sunday 10:00: drift scan. Compares contracts against actual implementation for drift.
- Sunday 05:00: restore drill. Actually restores a backup repo bundle.
- Hourly at :05: launchd watchdog. Checks that other jobs have checked in on schedule.
- Every 48 hours: repo health check.
- Daily 04:00: packages the entire repo as a bundle and uploads to R2.
The crontab has 7 more entries, mainly for data fetching and three offsite backup destinations. Four git hooks are attached (commit-msg, pre-commit, post-commit, pre-push), backed by 11 scripts: gitleaks secret scanning, PII gate, URL boundary check, wiki schema enum check, skill version gate, AI-tell lint, and four post-commit skill sync scripts.
The Cowork side has 39 scheduled definitions, 11 still active: an 8 a.m. control-tower briefing, a 9:38 a.m. scan for operational alert emails, a 9:45 a.m. check of whether the Fitbit token has gone stale, a 10:09 a.m. wiki content pipeline, a 10:35 a.m. cross-project governance roll-up, an 11:33 a.m. thematic synthesis of that day’s reading notes.
Boris’s routines mostly look for things to fix: crashes, duplicate implementations, dead code, flaky or pointless tests. Mine mostly confirm that things are still alive: contracts unbroken, mirrors undrifted, backups restorable, heartbeats intact.
The difference comes from scale. Anthropic has a team to review those 388 PRs. I don’t. With only myself, the order has to be reversed: buy the insurance first, then talk about productivity.
If the Routine Runs Every Day, How Do You Know It Is Actually Working?
Boris’s thread discussed results. It did not discuss one thing: when a routine itself goes wrong, who tells you?
I have hit three varieties. All three share the same surface appearance: everything looks fine.
The first: the action ran but had no effect. The original article described a data-update script running every weekday at 14:10, including git add data/timing.json data/stock.json. I connected roughly 90 days of missing version-control updates to the files being added to .gitignore on April 28, 2026, and errors hidden by 2>/dev/null. Those points need separating. Git’s official documentation says ignore rules do not stop already-tracked files from being tracked. Explicitly naming ignored, untracked paths can make git add fail. The available material does not confirm the files’ index state at the time or whether another operation removed them from tracking. The 90 days and script behavior remain the original author’s account; the specific Git cause is unconfirmed and cannot be inferred from ignore rules alone.
The second: the alert genuinely fired, but it was false. The launchd watchdog checks every hour to see whether other jobs have checked in. I use a laptop. When the lid closes and the machine sleeps, launchd does not make up the missed beat, so the watchdog reports a gap. Early on I investigated every single one conscientiously. After a few rounds I realized I needed to cross-reference pmset’s sleep log first. The routine that scans alert emails each morning now has this correlation built in: it asks whether the machine was asleep during that window, and only escalates to a real incident when the machine was awake and the heartbeat was still missing.
The third: the watchdog itself broke and still reported all clear. That was August 9th.
These three failures share one property: exit code green, logs full, dashboard lit. And the intended thing did not happen.
This is where automation is most expensive: the way it fails looks identical to the way it works.
It is tempting to attribute these failures to unclear task boundaries. But each of the three tasks above had perfectly clear boundaries: whether two files entered version control is binary; the expected status for each of 116 endpoints is hardcoded; whether the exit code is 3 is not a matter of interpretation. They failed silently anyway.
The dividing line is whether verification stands outside execution. In the original incident account, execution and reporting lacked an external check of the result. Before reconstructing the specific Git state, the lesson I can retain is this: a trigger and a log do not establish that the files entered the expected commit.
The PR flow Boris described happens to fill exactly this gap. A PR, plus Claude Code Review, plus human review, plus CI, forms an external, auditable verification interface. A routine cannot declare itself done unilaterally. The review process is documented; the numerical gap does not explain why PRs remained unmerged and is insufficient to establish that verification worked. Without that same checkpoint on my end, I had to build a separate set of routines whose only purpose is verification.
There is another difference tied to the character of the routines themselves. Offensive routines have visible output, and if a PR wasn’t opened today, you can see that immediately. Defensive routines, when working correctly, produce nothing. And “nothing because everything is fine” is externally indistinguishable from “nothing because the routine never ran.”
So roughly half the things I’ve added since exist to confirm whether something got done. The contract test compares against a hardcoded contract file, checking returned status codes one by one, asking the system a question, not accepting its self-assessment. The restore drill actually restores a backup every Sunday, because a backup that has never been restored is not a backup. There is also a chaos drill runner whose job is to manufacture failures and verify that alerts actually fire.
These routines produce no content and no features. Their only function is to prove that other routines are not lying.
This is the lesson I carried out of the automation cascade failure I wrote about earlier: once the number of automated components exceeds any single participant’s mental map of the system, the primary source of failure shifts from “a component broke” to “all components are functioning correctly but none of them know what the others are doing.”
Twenty-Eight of Those 39 Scheduled Jobs Are Already Off
There is one more thing Boris’s thread did not get into, something enterprises would do well to face early. Routines expire.
Of my 39 Cowork scheduled definitions, only 11 are active. Among the 28 that are off: some were one-time reminders (change a cron before an event kicks off; a note to upgrade the wrangler version on a specific day). Some were merged, and three wiki-related schedules consolidated into a single daily pipeline on April 23rd; three GSC-related ones became a single monthly review on July 5th. Some ended when the project did.
Every disabled schedule has one line in its description field: deactivated on [date], replaced by [what]. Six months from now I will have forgotten why two scripts appear to be doing the same thing. That line is all I will have.
Enterprises adopting agent routines will hit the same problem at larger scale: nobody remembers why the thing that runs at 6 a.m. every day exists, and nobody dares turn it off.
Key Numbers
- Anthropic’s side: 388 PRs in a few weeks, 180 merged (roughly 46%), 11 routine types spanning 6 platforms
- My side (historical account, not a new inventory): 23 launchd jobs, 7 crontab entries, 4 git hooks backed by 11 scripts, 11 active among 39 scheduled definitions
- Longest silent failure latency: roughly 90 days (the original author’s account; the specific Git cause remains unconfirmed)
Swap the Codebase for an ERP. Does This Transfer?
The abstract shape of Boris’s setup looks like this:
Find anomaly → trace cause → propose fix → verify → record → human approval → execute
Swap the codebase for an ERP, an MES, a CRM, an ESG report, or financial and procurement data, and this flow can still hold. People do not have to ask the AI every day; agents can check periodically: are there reconciliation anomalies, is inventory turnover drifting, are supplier carbon figures missing, are customer complaints clustering into a repeating pattern?
At this point, an enterprise adopting AI is no longer adding a few more tools. It is beginning to manage an operations organization that never goes off shift.
Two things must travel with the migration, though, or it will go wrong.
The first is permission tiering. The ratio alone does not show whether the process was healthy or the output poor; the reasons for non-merging and actual acceptance results are still needed. An agent architecture needs risk-tiered routing: low-risk mechanical work can execute automatically; medium-risk changes go into review; high-risk actions require human approval. Changing a report column in an ERP and changing a posting rule are not the same operation and should not follow the same path. I worked through the logic behind this in the Governance Harness piece: every layer of automated defense corresponds to a documented record of a prior lapse in discipline.
The second is what this whole piece has been about: when you migrate the routines, bring the verification layer with them. Enterprises evaluating a deployment typically model the benefits of the first half and rarely build contract tests, drift scans, or restore drills into year-one budgets. Before anything breaks, those look purely like waste.
Software has an easier time here, and I think some of that is luck. The PR is a twenty-year-old mechanism that happens to be a ready-made, external, auditable approval interface: who proposed it, what changed, who reviewed it, who pressed merge. The full chain lives in the system. Boris’s setup can run in part because it stands on this existing foundation.
ERP, MES, and CRM systems generally have no direct equivalent. Change management does have approval workflows, but they were designed around the frequency of human actions and may not be able to handle the volume an agent generates daily. System logs record events; records alone are not approval. When enterprises try to transfer this pattern, the first question may not be which model performs better, but how to design a governance interface for their own systems that works the way a PR does.
The Half That Cannot Be Delegated
Boris’s line about modifying the routine when the first attempt isn’t right so that Claude does better the next day is the heaviest sentence in the whole thread. It means the asset accumulating over time has shifted from code to operational knowledge.
But operational knowledge has two halves.
One half is how to do a job well. Agents learn this quickly. Boris said sometimes a few days of adjustment is enough.
The other half is how to confirm the job was actually done. Execution, and part of verification, can go to the agent. But the standard of acceptance cannot be defined solely by the system doing the work. If it is, you have not merely lost one check. You have lost the second independent perspective.
I reached a similar conclusion in the piece about having Codex critique Claude’s output: a second opinion is only useful if you protect its independence. Operations work by the same logic, just at larger scale and with no one available to do a retrospective review.
If the previous phase was AI helping people write code, this step differs in that people are beginning to hand off the work of maintaining systems itself. The implications may run deeper than coding agents, because maintenance runs across the entire software lifecycle and typically outlasts the original build by years.
This piece is part of the Intelligence and Order series on human-machine collaboration. Under the same pillar I have written about what happens to judgment when a tool becomes an organ and about governance practice when one person runs four AI windows simultaneously. This piece adds the third piece: when an agent starts showing up for work on its own, you need a way, independent of the agent, to know whether it actually did anything today.
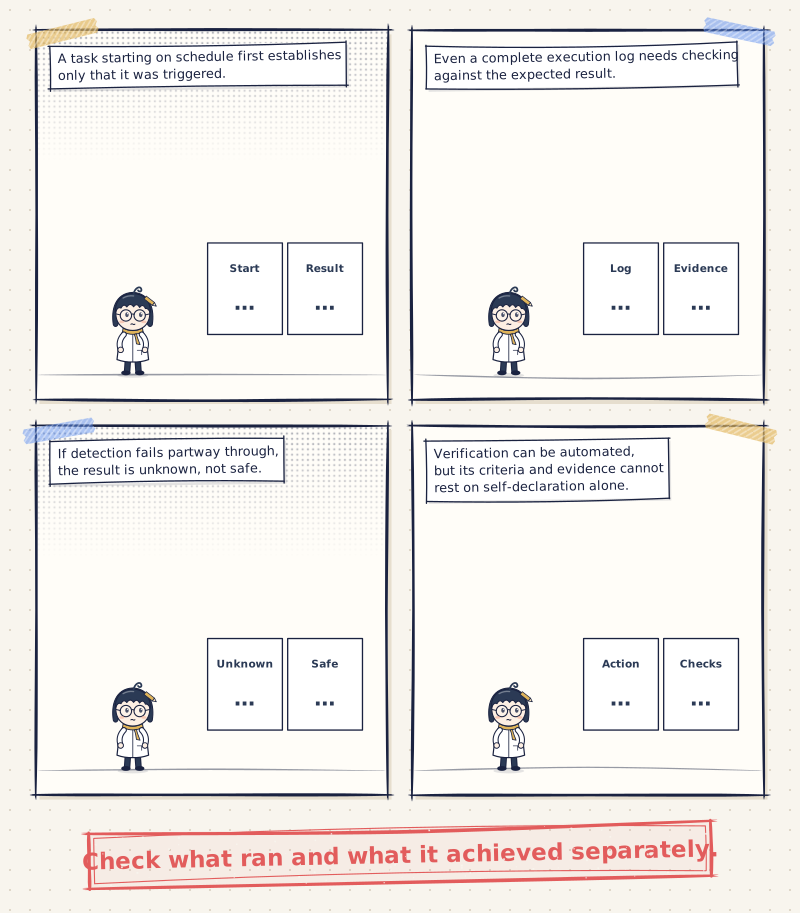
Leave evidence of the result
A running routine does not prove the work is done.
A task starting on schedule first establishes only that it was triggered.
Even a complete execution log needs checking against the expected result.
If detection fails partway through, the result is unknown, not safe.
Verification can be automated, but its criteria and evidence cannot rest on self-declaration alone.
Check what ran and what it achieved separately.
Revision and source boundaries: November 4, 2026. The PR period and figures were checked against the third saved thread screenshot. The original Threads link could not be read this time; its relative timestamp does not establish an absolute posting date. Personal metrics, incident details, and roughly 90 days remain historical accounts. Private logs and the past index state were not rechecked. Older animations containing the unconfirmed Git explanation are being replaced; this revision is not a fresh verification of the incident.
Tomorrow Morning They Will Wake Up Again
At the close of the original article, I imagined those 23 jobs waking on schedule the next morning, running, sending a heartbeat, and going back to sleep. On most days they would find nothing. That was how it should be.
What I watch for is something else. On August 9th, if I had not happened to check, that “no divergence” string might still be sitting there today.
On time every day. All green every day.
And every day, answering a question it never finished verifying.

💬 Comments
Loading...