If live meeting translation runs, how can I tell which stage makes mistakes, what it costs, and where the audio and text go?
I want to replace “building it myself must be cheaper” with “how is each part checked?” Recognition, translation, display, and export can be considered separately, alongside costs, data flows, and maintenance responsibility.
1. Define the help needed during the meeting
Post-meeting transcripts, live captions, another language’s translation, summaries, and action items are different needs. If a hypothetical meeting only needs live comprehension, a complete content platform need not become the first version’s goal.
Specify whose voices, which languages, one-way or two-way use, and the devices people will read on. These are design questions for a hypothetical tool, not verified claims about a product’s supported features.
Breaking down requirements does not rank it above programming or security checks. Requirements, engineering, quality, and maintenance need each other. A clear prompt cannot remove the other work.
2. Check recognition, translation, display, and export separately
First examine how audio becomes source text, then how source text becomes a translation, what users see, and what is exported. This is the author’s proposed check sequence, not a claim that an existing tool has completed it.
If source text is wrong, fluent translation may carry the error forward. Correct source text does not guarantee correct tone, terminology, or names. Slow captions, incorrectly joined passages, and missing exported text are further issues.
A hypothetical short meeting excerpt could be checked at each stage with appropriate authorization, recording errors along the way. No new test was performed here, and no accuracy rate or speed multiple without a defined test set and rules is used.
3. Align cost scopes before comparing
No separate development payment does not mean zero cost. APIs, subscriptions, deployment, manual setup, error handling, and ongoing maintenance can all need recording. Exclusions should also be stated.
Per-meeting estimates need duration, languages and directions, actual audio or text usage, retries, dated unit prices, and exchange rates. Those records were not checked in this revision, so no new per-meeting price is given.
Building and subscribing also need comparison over the same service scope. Partial API spending divided by a complete subscription fee cannot establish which option is cheaper long term. This essay does not republish current competitor prices or rank plans.
4. Login, data flows, and maintenance are separate questions
Being able to sign in and restricting access do not establish clear limits for audio and text use. I would separately ask how microphone or meeting audio is obtained, whether participants understand its purpose, and which data reaches which services.
Then ask where information is stored, for how long, who may read it, what exports contain, and how deletion or stopping use is handled. These are design and responsibility questions, not claims that a particular tool meets a law or security certification.
When a service or interface changes, someone still needs to detect failure, investigate, and choose alternatives. An automated workflow does not establish ongoing maintenance. A model’s claim of completion also needs corresponding records.
5. Four questions for a meeting-translation tool
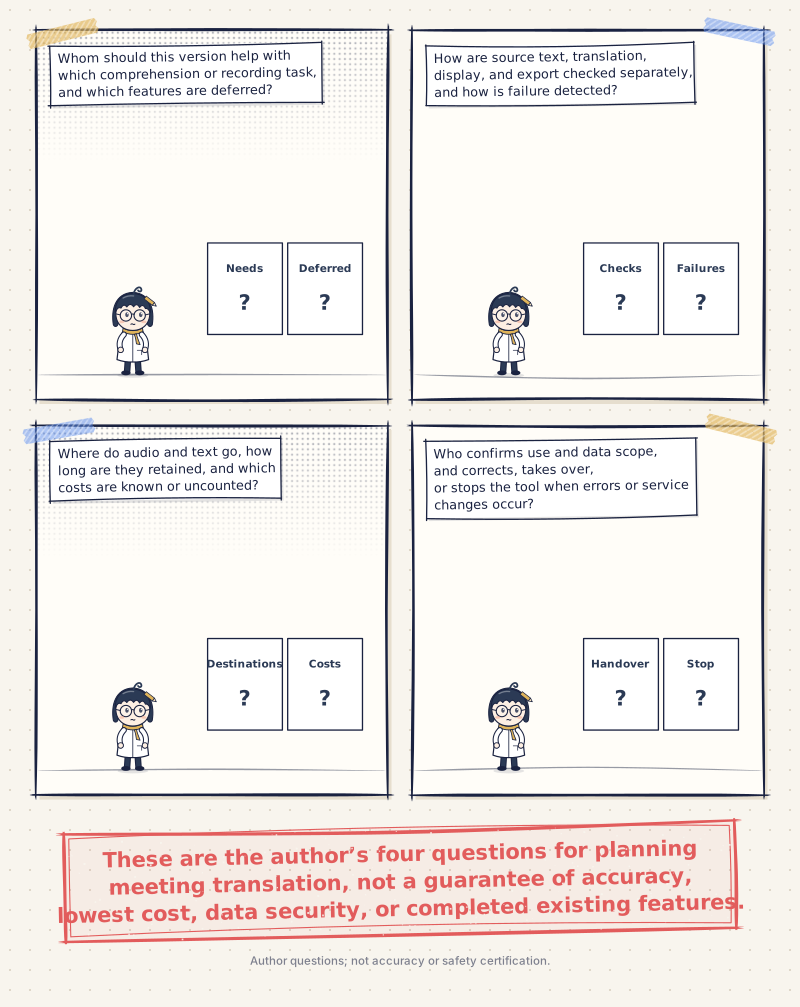
- Whom should this version help with which comprehension or recording task, and which features are deferred?
- How are source text, translation, display, and export checked separately, and how is failure detected?
- Where do audio and text go, how long are they retained, and which costs are known or uncounted?
- Who confirms use and data scope, and corrects, takes over, or stops the tool when errors or service changes occur?
These are the author’s four questions for planning meeting translation, not a guarantee of accuracy, lowest cost, data security, or completed existing features.
6. Leave collaboration where it can be checked and handed over
AI can help discuss requirements and produce code. I also want checkable roles, stage results, and unfinished items retained, so the next person need not reconstruct everything from “it is done.”
If one stage has passed, describe that stage clearly. If data or costs are incomplete, retain the unknowns. That helps readers assess a tool more than an attention-grabbing claim of zero cost or a dramatic multiple.
Writing and revision scope: Revised November 4, 2026. The earlier article becomes the author’s design and collaboration reflection. Private subscription invoices, development logs, code, and historical deployments were not reconstructed; competitor prices and paid APIs were not newly tested. Zero-cost claims, NT$16 per meeting, one-tenth costs, subscription totals, meeting counts, accuracy rates, speed multiples, language counts, routing-completion claims, and the old architecture diagram were removed. Removal does not establish that earlier events never happened. Stages and data questions are hypothetical acceptance suggestions; the four questions are not experiment results, product recommendations, or legal or security certification.

💬 Comments
Loading...