Can a model winning a few tests be converted into “surpassing humans in another six years”?
The original article resisted a rapid AGI countdown, yet also used inadequately sourced figures to conclude that six years was necessarily too optimistic. Both approaches share a problem: jumping from a partial observation to an insufficiently defined destination.
This revision does not assign AGI another arrival date. I want to retain the habit of asking what was actually compared when reading about a capability breakthrough.
TL;DR: Grok-2’s 2024 results are historical information about particular versions, tests, and comparators, not today’s ranking or an AGI countdown. Nor can this article announce a single universally accepted AGI definition. The original claims about training costs, improvement rates, and exhausted data need correction. Resource constraints matter, but do not establish that six years must succeed or fail. My suggestion is to check definitions, tests, projections, and deployment authority separately.
1. Put Grok-2 back into its 2024 announcement
xAI published its Grok-2 beta announcement on August 13, 2024, saying an early version outperformed comparators including GPT-4-Turbo in overall Chatbot Arena Elo at that time.[1] The original article’s “late 2024” dating was inaccurate and is corrected here.
This was the vendor’s announcement then. It does not mean outperforming every GPT-4 version on every task, or retaining the same position today. The announcement’s academic benchmark table itself shows varying strengths and weaknesses; one good result is not comprehensive leadership.[1]
I would narrow the questions: which version, questions, and tools were used? Against whom? Were conditions comparable? Answering these first shows which part of the work the improvement actually covers.
That does not diminish testing. It keeps tests within the scope they can support.
2. Specify which ability is surpassing humans
“Faster than one person,” “high-scoring on a particular exam,” and “able to handle many different jobs” are different claims. Without a comparator and scope, “surpassing” becomes a word everyone understands differently.
Levels of AGI proposes a research framework that classifies depth of performance and breadth of capabilities, while discussing capability separately from deployment autonomy.[2] It is one operational proposal, not the sole accepted definition. This article also does not transfer its historical model classifications into a judgment about 2026.
The original article overstated self-directed goals, self-improvement, and understanding human values as necessary AGI criteria. They merit research or governance, but cannot be declared shared thresholds across the field without explanation.
The value trade-offs I care about remain important. But “what a system can do” and “what we allow it to decide” need separate questions; redefining intelligence cannot merge them.
3. Using new information need not require retraining every time
The original changing-tournament example asserted that a model could only wait for new training data. That was too absolute. xAI’s announcement already discussed retrieved content and tool use; we cannot cite its scores while omitting those conditions.[1]
Consider an explicit hypothesis instead: we put new rules for a fictional competition into a prompt and ask a model to analyse strategy. Whether it uses them correctly can be tested. That is different from updating model parameters.
Likewise, a search tool does not guarantee current information, trustworthy sources, or correct interpretation. I would check whether the data were actually obtained, the right version cited, and the new conditions correctly applied. One correct answer does not establish general adaptation, and a training cutoff does not mean new information can never be handled.
This example is my checking suggestion, not an experiment completed on a particular current model.
4. Correct the cost and retain assumptions about constraints
The original claim that GPT-4 training required “hundreds of billions of dollars” had no supporting basis. AI Index 2025 estimates roughly USD79 million using information such as cloud compute rental prices. This is an estimate, not the developer’s actual invoice or all research, hardware, and operating expenditure.[3]
The original “Google research” claim that annual improvement fell from 40% to 10% identified neither a study nor a measure. This check found no adequately verifiable source, so it is withdrawn.
Data supply should not be described as already exhausted either. The AI Index discussion includes assumptions about usage, repeated training, and methods; predictions change with conditions.[3] Constraints deserve monitoring, but this evidence alone cannot establish an industry-wide plateau.
I do not turn this correction into proof of unlimited growth. It means an argument for a deadline cannot depend on erroneous costs and unverified trend lines.
5. Six years is a prediction requiring its own evidence
The original article did not retain a traceable quotation, date, and endpoint definition for “six years.” This revision supplies no countdown starting point and does not continue attributing it to someone as a verified quote.
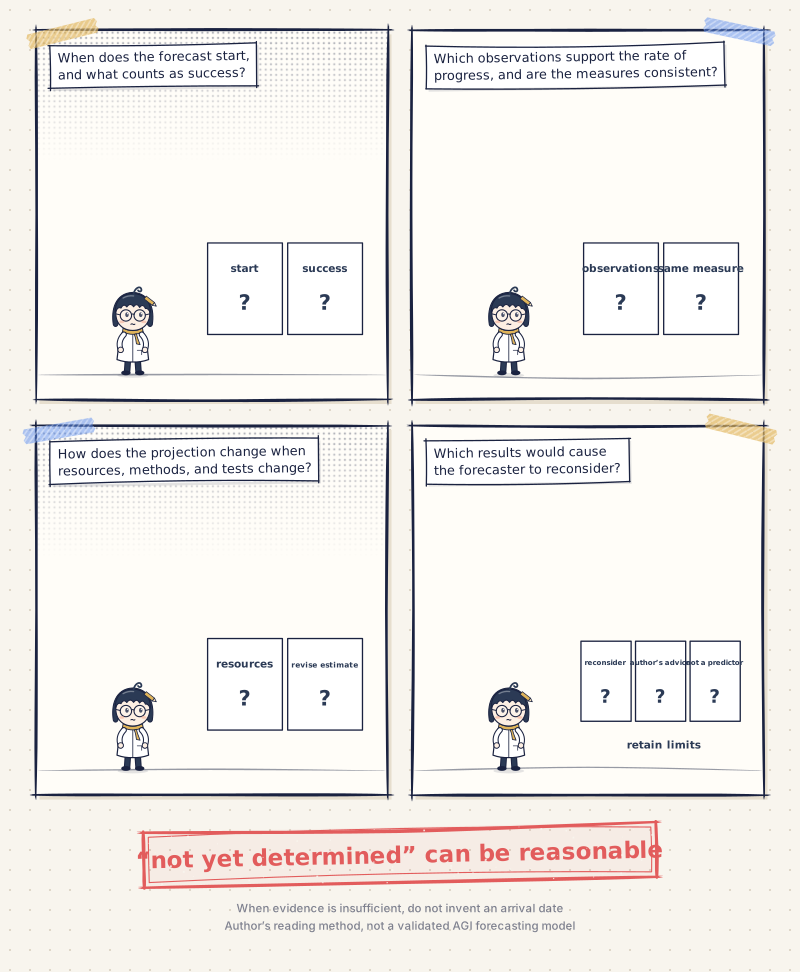
When someone proposes a deadline, I would first ask four things:
- When does the forecast start, and what counts as success?
- Which observations support the rate of progress, and are the measures consistent?
- How does the projection change when resources, methods, and tests change?
- Which results would cause the forecaster to reconsider?
These four questions are the author’s reading method, not a validated model for calculating AGI’s arrival. With insufficient evidence, “not yet determined” can be reasonable, rather than rushing to six years, ten years, or never.
Questioning a timetable does not prevent taking changes in capabilities and risks seriously.
6. Reserve some countdown attention for today’s verification
For AI users, I care more about which work can be delivered today, which outcomes still need review, and who may adopt or stop an action. These questions need not wait for agreement on AGI’s definition.
My practical suggestion is to define the task and acceptance criteria first, record versions, data, and tests, and check whether capabilities actually transfer when the situation changes. Important actions need separately designed permissions; high scores should not automatically relax them.
This is not a universally validated governance standard. It is how I hope to avoid being led by a single score.
I still look forward to AI progress and remain curious about predictions. But the next time I read “surpassing humans within six years,” I will first ask: surpassing them at what?
Sources and reading boundaries (checked through November 3, 2026)
- xAI, Grok-2 Beta Release: historical vendor announcement, August 13, 2024. Date, comparators, evaluation conditions, and retrieval/tool sections checked; not a 2026 ranking or independent replication.
- Morris et al., Levels of AGI, v5: September 24, 2025 version. Definitions, performance/generality, and capability/autonomy distinction. One research framework; historical model classifications are not current judgments.
- Stanford HAI, AI Index 2025, Chapter 1: printed page 43 on training costs, appendix estimation methods, and pages 37–38 on data supply. Historical estimates and conditional projections; no actual cost audit, replicated estimation, or comprehensive later-data verification.

💬 Comments
Loading...