If a system runs automatically every day but stopped producing useful results long ago, how would we notice?
I once wanted a website to modify its own settings, score itself, and keep better versions. Reviewing that effort made me reconsider more than the code: how far was the score from what I actually wanted to achieve?
This essay retains the retirement lesson while separating technical failures, scoring design, and the direction of a personal website. It neither turns one case into a law for all sites nor declares multi-AI discussion an official new version of someone else’s research.
TL;DR: Autoresearch can inspire a workflow of proposing changes, experimenting, evaluating, and keeping or discarding results. This site tried a similar approach, leaving problems with a truncated file and monitoring useful output. Verifiable version changes do not establish the full runtime cause. Whether a proxy score reflects real website outcomes is a second question; the author’s strategic choice is a third. Independent perspectives, source checks, and human decisions are my collaboration arrangement, not a validated autoresearch v2.
1. Explain autoresearch and the terms first
In the fixed version of Karpathy’s project consulted here, autoresearch lets an agent modify a small language model’s training code, measure the result within a fixed five-minute training budget, and keep or discard the change. Startup and compilation are excluded. It uses a single-GPU setup and a particular validation metric.[1]
Here, a mutation is a candidate modification, and reward is feedback used to judge improvement. A model validation metric has a specific purpose; substituting a website score does not guarantee improvements to every website objective.
I once applied a similar idea to this site: propose changes to specified site files, build, and score them. That was my implementation, not a method already validated by the original project for personal branding.
This essay does not reconstruct the project’s initial release date or use an unverified long social-media quotation to establish official v1/v2 relationships. Borrowing a method still requires explaining what was borrowed and changed.
2. Examine technical records rather than explaining a failure through strategy
The site’s Git history confirms that a March 23, 2026 change reduced experiments.json from a populated file to zero bytes. The May 13 retirement change moved the old directory, added a retirement notice, and removed the old workflow.[2]
The original account says I looked back on May 12 and noticed the lack of expected progress. “About seven weeks” describes the delay in noticing, not seven weeks of normal operation followed by failure.
A file becoming empty does not by itself establish the cause of every later failure. Relationships among excessive inputs, incorrect paths, scoring, and record keeping require contemporary execution evidence. I have not rerun the entire history or established that every notification channel has been examined.
The lesson is that a triggered schedule does not establish useful output. Checking whether a process ended without checking outcomes and data completeness can leave us thinking work is advancing when it is not.
3. A better score and a better real outcome are different questions
I once included machine-readable files and structures in website scoring. But that score differs from whether readers understand the content, whether it is reliable, and whether collaborations occur.
Passing a format check alone cannot establish that people become more willing to cite or collaborate. Conversely, missing evidence of an effect does not make every machine-readable design worthless.
The original inferred that leading personal sites do not use mutation engines from observations about llms.txt. That exceeds the evidence. This version drops that industry-wide conclusion and does not use research on one file type to establish a ceiling for all website optimization.
This level asks whether a score suits its objective; it does not explain March’s file truncation. Even if all code is repaired, the score’s purpose still needs separate examination.
4. Different website objectives call for different comparisons
I distinguish several needs in my work: whether a tool completes its task, whether an article is understandable and well sourced, and whether a personal site supports the relationships I want to build.
Completion rates or continued use might be useful observations for a tool; correctness, readability, and updates can be checked for content. These are my suggested design directions, not claims that v0, Builder’s Scorecard, or another named product actually runs the autonomous scoring loop described here.
Collaboration invitations and trust may not quickly yield stable scores for me. Whether that automatic site-modification system was worth maintaining therefore needed consideration alongside costs, risks, and other possible work.
That was a strategic change in my own case, not proof that all personal websites are unsuitable for automation. Different objectives and time scales call for explicit comparisons, rather than a verdict on a whole category.
5. Bring different perspectives in, then check their claims
During that review, I used different collaboration interfaces to examine concepts, engineering, and file records separately, then synthesized the findings and made the trade-offs myself. Chat, Cowork, Codex, and Code were roles in that workflow; Paul is me, the author.
The arrangement aimed to let different checks reveal omissions. It does not guarantee an absence of shared blind spots or permanently define a tool as conceptual and incapable of finding engineering facts.
I can call it my own multi-party deliberation. Several agents producing reports do not reproduce the original project’s controlled experiments or establish an official v2 endorsed by Karpathy. Recommendations still need checking against files, sources, and actual results.
I retain a responsibility arrangement rather than confidence that model agreement proves truth: differing views can be preserved, people explain what they adopt, and someone owns execution and acceptance.
6. Ask four testable questions before automating
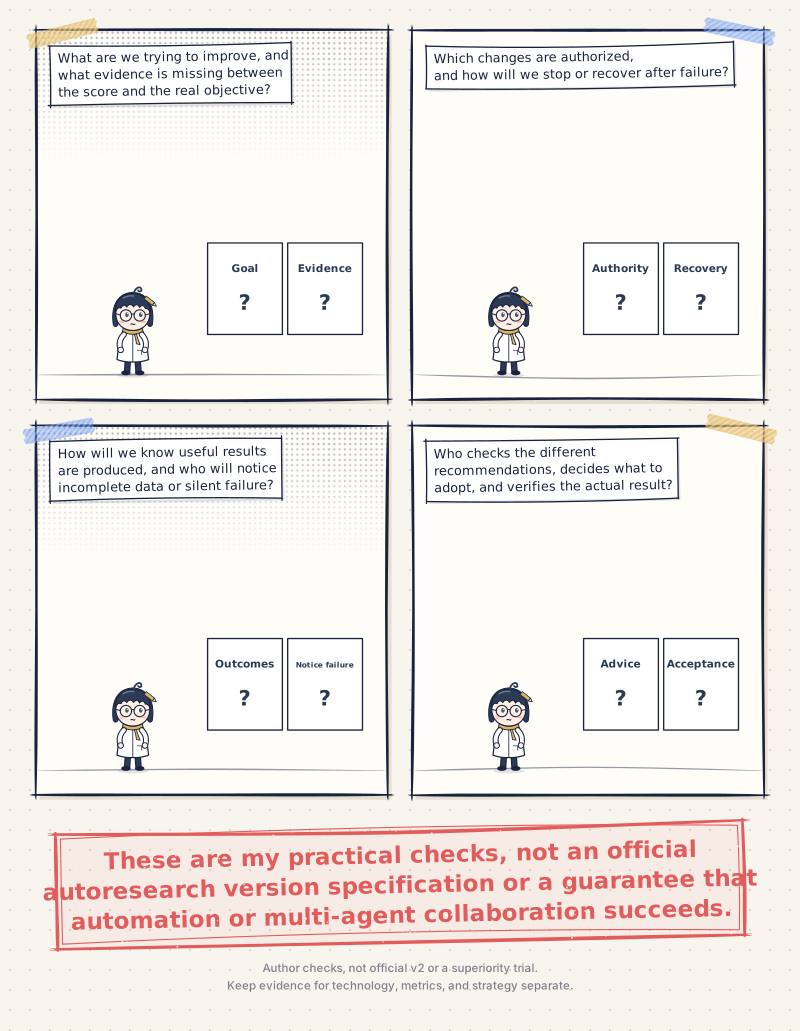
Before applying a similar approach to the next job, I would ask four questions:
- What are we trying to improve, and what evidence is missing between the score and the real objective?
- Which changes are authorized, and how will we stop or recover after failure?
- How will we know useful results are produced, and who will notice incomplete data or silent failure?
- Who checks the different recommendations, decides what to adopt, and verifies the actual result?
These are my practical checks, not an official autoresearch version specification or a guarantee that automation or multi-agent collaboration succeeds.
Retiring an implementation does not mean rejecting research and experiments. I simply want the next attempt to check what the system accomplished, even when the terminology sounds excellent.
For me, a workflow that notices failures, checks recommendations, and takes responsibility matters more than whether a website can modify itself.
Sources and reading limits (checked through November 4, 2026)
- Karpathy, pinned autoresearch README, commit
228791fb499afffb54b46200aca536f79142f117, March 26, 2026; How it works and Design choices. Supports the small single-GPU training setup, fixed budget, and evaluation method—not website outcomes, official v2, or superiority of this collaboration arrangement. The project was not executed. - This site’s Git history: the March 23, 2026 file change, identified in the original as
bfacd167, and the May 13 retirement change. File sizes and version operations were checked. The repository is private and no public reproduction package is supplied; complete execution records, notifications, and failure causation were not reverified. The May 12 discovery and multi-party review remain the author’s contemporary account, without added private conversations or meeting durations.
Revision note: This version separates delayed discovery, technical failure, scoring mismatch, and strategy. It withdraws industry-wide claims, unverified product loops, long social-media quotations, and official-v2 claims. Retirement and multi-party checking remain experiences, not universally applicable methods or causally validated research.

💬 Comments
Loading...