How much work still lies between asking AI to make a software prototype and handing that prototype to someone else to use?
When people discuss vibe coding, I think this distance is what gets left out most easily. Conversation lets us see the outline of an idea more quickly, but whether a feature is correct, how data is handled, and who can fix it when it fails still need to be checked one by one.
The opportunity in “code getting cheaper” lies here: we can reassess which ideas are worth trying, and we need to distinguish which part of the cost we have actually saved.
Vibe coding makes experiments easier to begin
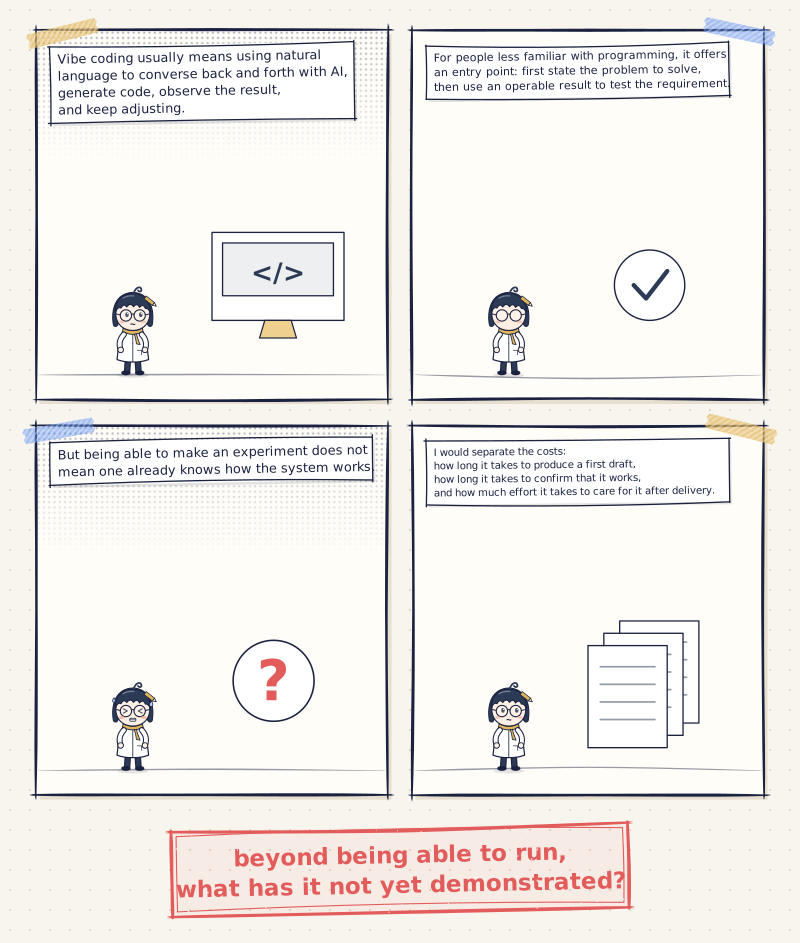
Vibe coding usually means using natural language to converse back and forth with AI, generate code, observe the result, and keep adjusting. Collins chose it as its Word of the Year for 2025, reflecting how this way of working has entered public discussion.
For people less familiar with programming, it offers an entry point: first state the problem to solve, then use an operable result to test the requirement. Once a screen and a flow appear, people can often identify more easily what is wrong.
But being able to make an experiment does not mean one already knows how the system works. If a result is judged only by whether it “looks fine,” problems that do not appear immediately, such as bad input, permissions, or data retention, may be missed.
Producing code is cheaper; delivery still has costs
In “Writing code is cheap now”, Simon Willison draws a clear distinction: AI lowers the cost of producing code, but good software still needs validation, error handling, testing, maintenance, and a solution to the right problem.
This distinction is more useful than saying that a year of work has been compressed into an hour. Producing an implementation quickly does not directly mean that clarifying requirements, trying and correcting errors, integration, and ongoing maintenance have all become equally short. To compare efficiency, we need at least to know whether the two deliveries have the same scope.
I would separate the costs: how long it takes to produce a first draft, how long it takes to confirm that it works, and how much effort it takes to care for it after delivery. Only by looking at all three can we avoid treating the speed of writing as the result of the whole project.
Things that were not worth doing can be assessed again
Ideas once set aside because development would take too long may now be worth reassessing through a small, bounded experiment. The point is to keep the cost and consequences of the experiment within a range we can bear.
For example, a small tool that processes test data only on a local machine needs a different level of confirmation from a system that changes customer data. The former can begin by asking whether it solves the problem. The latter must also address authorization, error recovery, and responsibility.
This is how I reason from the change in costs: first narrow the question to be verified and let the prototype answer it. Cheaper experiments make it possible to try more directions. But after a prototype succeeds, we still need a separate decision about whether formal delivery deserves investment.
From writing code to letting an agent keep working
Personal AI assistants take the question a step further. When an assistant can keep receiving tasks, use tools, and retain working context, people are managing more than a piece of code. They are managing what it is allowed to do.
The difference becomes clear in a single request. Asking AI to write a tool that looks up train schedules and authorizing an assistant to book a ticket for you are different degrees of delegation. The latter involves time, fare type, payment, and cancellation terms; it cannot be covered by “it should know.”
That is why the next step I care about is making permissions explicit: what data can be read, which actions can be carried out independently, and which results require human confirmation. The more tools are connected, the more these questions need answers before use.
Judgment in knowledge work also needs checkable results
The same question appears in writing, design, and data analysis. AI can help produce candidate work, but we still need to say what counts as good: whether an article has support, whether a design solves a user’s problem, and whether an analysis answers the original question.
Judgment also needs to land in concrete work. Pointing out which sentence lacks a source, which flow will leave a person unable to continue, or which number was calculated incorrectly helps collaboration more than the broad claim that “humans must retain judgment.”
The next time I think an idea is not worth developing, I will first ask: can a small prototype show whether it is worth continuing? Before delivery, I will ask again: beyond being able to run, what has it not yet demonstrated?

💬 Comments
Loading...