If one AI writes a website and another says “no problem,” has cross-checking been completed? I want to separate production, questioning, and acceptance first.
What attracts me to working with multiple models is examining the same problem from another angle. But another answer does not automatically supply another piece of evidence. Making a website readable for people and usable by tools also requires distinguishing the purposes of different tasks.
1. Start with what readers need to do
I want an article to let people find its claim, see its basis, and recognize uncertainty. Fonts, letter spacing, line spacing, and paragraphs support that goal. They need not begin with one universal aesthetic for every Chinese or English reader.
Reading experience also cannot be judged from a homepage screenshot alone. A hypothetical article-page revision could examine long mobile headings, line breaks, recognizable links, and readers’ ability to return to a passage. These are acceptance questions, not website features newly completed here.
Observable actions make needs easier to discuss than “more order.” Models can suggest layouts; the author still needs to inspect actual pages and decide which suggestions fit the content.
2. Roles are task assignments, not fixed model personalities
One model can propose an implementation and another look for problems against the same requirements, with a person deciding what to do. Claude and Gemini were tools discussed in the earlier article. This essay does not assign permanent “architect” or “validator” identities by brand.
Useful questioning needs a specific target: are sources missing, do examples match actual functions, and do displays match data? Asking again with a different prompt may simply produce another equally fluent endorsement.
I would retain suggestions and return to sources, code, or actual operation to check them. Model agreement does not replace author acceptance. Separating roles also does not establish that two models’ errors necessarily cancel out.
3. Page structure, data descriptions, and tool calls are different tasks
HTML headings, paragraphs, and sections organize a page. Whether its structure fits depends on content and actual use, not the number of tags employed.
Schema.org supplies a shared vocabulary for describing entities, relationships, and actions; JSON-LD is one available encoding. This gives descriptions such as article, author, and date a shared format. It does not make content correct or certify an author’s authority with AI.
WebMCP concerns another task: making callable tools available from a webpage to agents. Chrome’s February 10, 2026 announcement introduced an early preview. The November 2, 2026 community draft checked for this revision explicitly says it is not a W3C Standard. Neither source establishes that any particular website has implemented it.
4. Before saying a tool exists, examine what happens
Suppose a website wants agents to search articles. At minimum, explain inputs, outputs, the supported environment, and how failure appears. Mentioning a “search tool” in an article and demonstrating a callable tool in production require different kinds of evidence.
Where an operation submits information or changes state, appropriate user intent, permissions, and confirmation arrangements are also needed. These are responsibility questions recommended here, not a claim that a protocol has already provided those arrangements for a website.
This revision did not audit all website code or reconstruct February 2026 deployment records. It therefore does not retain claims that this site “complies with the WebMCP standard” or already exposes article search to agents. Nor does it conclude that all agents no longer need to read pages.
5. Four acceptance questions for collaboration
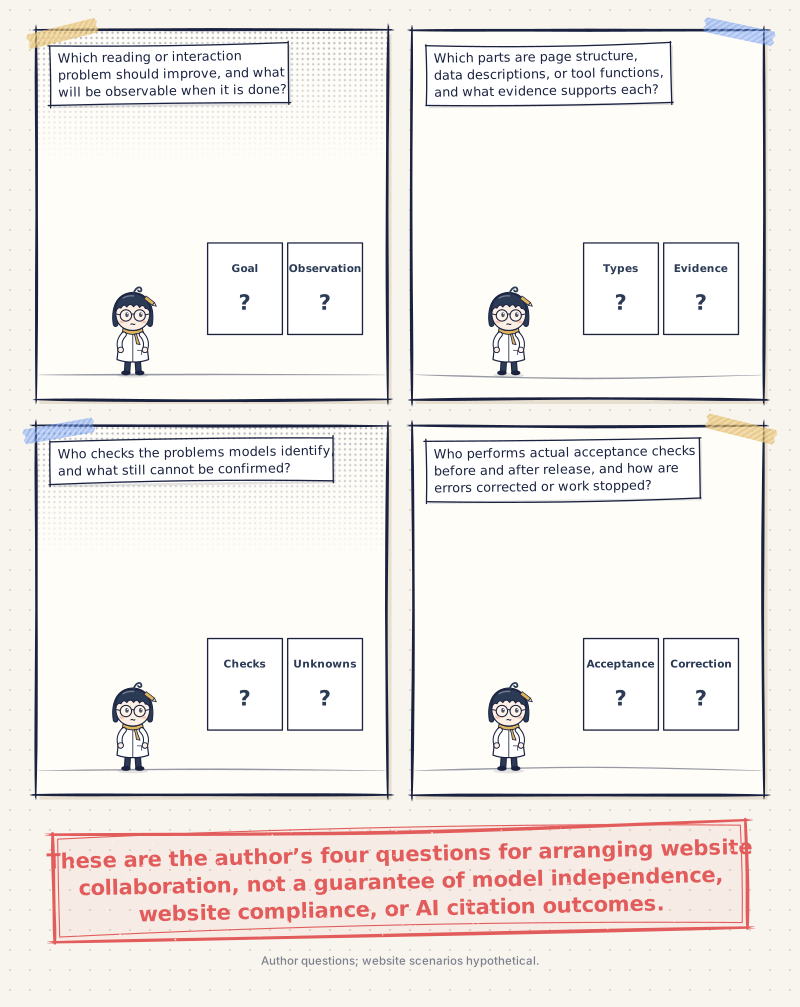
- Which reading or interaction problem should improve, and what will be observable when it is done?
- Which parts are page structure, data descriptions, or tool functions, and what evidence supports each?
- Who checks the problems models identify, and what still cannot be confirmed?
- Who performs actual acceptance checks before and after release, and how are errors corrected or work stopped?
These are the author’s four questions for arranging website collaboration, not a guarantee of model independence, website compliance, or AI citation outcomes.
6. Bring collaboration back to readers and actual use
I want to retain multiple perspectives and let tools participate in production. But results cannot be represented only by model praise, attractive screenshots, or standards terminology.
Whether readers can find content, data matches sources, functions actually work, and someone handles problems is more concrete than the label “shared human–machine reading.” Clarify those tasks before deciding whether another model or feature is needed. That gives collaboration a basis that can accumulate over time.
Materials and revision scope: Revised November 4, 2026. Necessary passages of Chrome’s February 10, 2026 early-preview announcement, the status, abstract, and introduction of the November 2, 2026 WebMCP community draft, and Schema.org’s purpose statement were directly checked. The latter is currently development V30.1, September 16, 2026, not a snapshot from the original publication. The full WebMCP specification, browser-support matrix, and this site’s historical implementation were not verified. Unverified collaboration timelines, completed-tool claims, a specific Chrome version, and citation guarantees were removed. Website scenarios are hypothetical; the four questions are the author’s suggestions. No website feature, model test, or private-record search was added.

💬 Comments
Loading...