When an AI company’s leader names several future years, should I read them as a forecast, a product goal, or results that can already be checked?
I want to separate those categories before considering whether the expectations are reasonable. Joining different sources into a prophecy coming true can sound powerful while pushing definitions, conditions, and evidence into the background.
1. Retain the conditions of the original statement
In Sequoia’s published AI Ascent 2025 transcript, Altman discussed a sequence involving agent work, scientific discovery, and robots’ economic value, while explicitly qualifying it as an offhand guess. It can be read as his outlook at the time, not a formal AGI countdown commitment.
What a forecast covers and how certain the speaker sounds should stay together. This essay has not verified the event’s month and day, so it uses the confirmed year rather than treating “last May” or “nine months later” as checked coordinates.
If a retelling keeps only the years and removes possibilities, expectations, and guesses, readers receive something more certain than the original statement.
2. Ask what a milestone means before arranging a ladder
OpenAI’s September 6, 2026 article reports reaching its research-intern goal, defined around well-specified research tasks under human direction. This is the company’s own measurement, not independent AGI certification.
I would treat that as a claim whose methods and scope need understanding, rather than arranging “intern,” “researcher,” or capability levels into a universal intelligence ladder. Different labels may address different questions. Titles alone cannot establish an upgraded or downgraded goal.
A company report offers an entry point. Whether it supports a larger conclusion still depends on methods and applicable conditions. This essay did not repeat the experiments or compare every product’s research capability.
3. Separate demonstrations, task completion, and reliable use
If a hypothetical tool organizes research materials, we still need to know whether those materials are correct, which parts had human guidance, how failure is defined, and whether the result transfers to another task. This is an evaluation scenario, not a new model test.
One attractive result cannot supply a success rate for every job. Product launches, version changes, and capability labels also cannot directly establish whether a particular task can be delivered under particular conditions.
I no longer use an “80% completion” claim without a shared task set, denominator, and scoring rules. Rather than give AI one overall score, specify the task, data, human intervention, and consequences of failure.
4. Separate future goals from today’s decisions
A timetable can suggest questions to prepare for; it cannot establish the case for adoption today. Resource planning can list dependencies and alternatives without declaring that an entire industry has fulfilled a forecast or must be delayed.
Infrastructure likewise needs distinctions among plans, pledges, contracts, financing, power availability, and actual operation. This essay has not verified the investment and capacity figures previously listed and does not use them to support conclusions about geopolitical order or public goods.
Physical operations need task-specific consideration of effects, oversight, and stopping conditions. This essay does not assign one tolerance level to all physical tasks or predict from an outlook that 2027 will necessarily bring fulfillment or delay.
5. Four questions for reading AI timetables
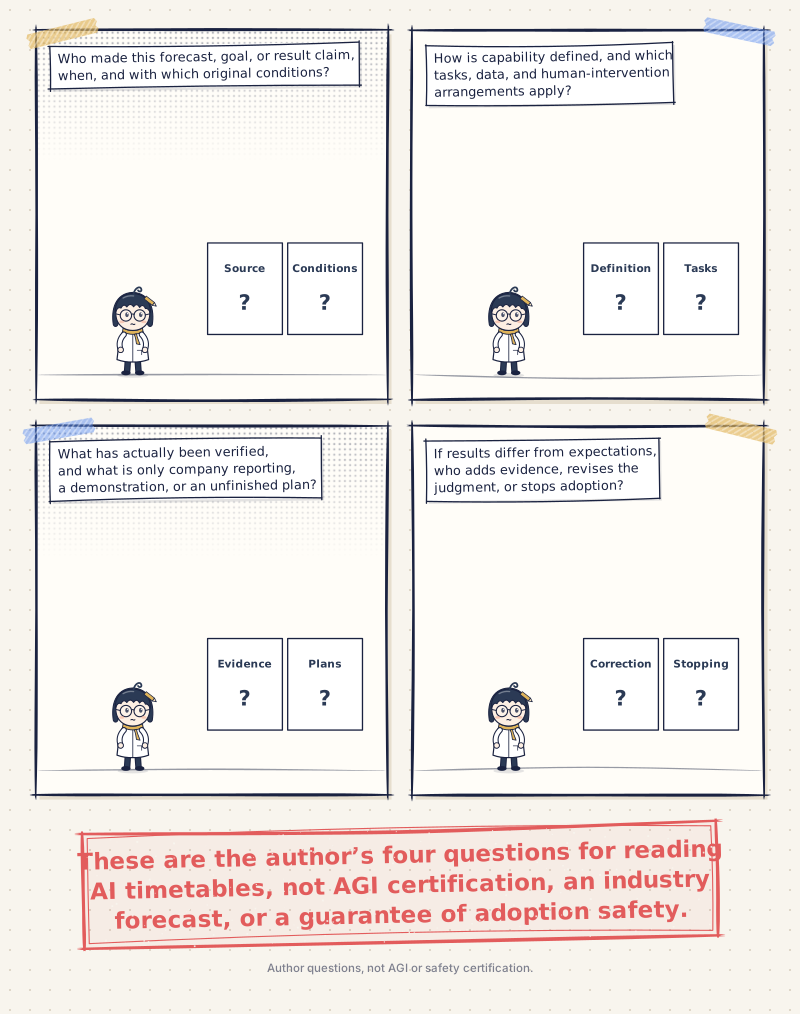
- Who made this forecast, goal, or result claim, when, and with which original conditions?
- How is capability defined, and which tasks, data, and human-intervention arrangements apply?
- What has actually been verified, and what is only company reporting, a demonstration, or an unfinished plan?
- If results differ from expectations, who adds evidence, revises the judgment, or stops adoption?
These are the author’s four questions for reading AI timetables, not AGI certification, an industry forecast, or a guarantee of adoption safety.
6. Keep expectations, and let conclusions change with evidence
I remain interested in where AI can take work and willing to read company outlooks. Believing in possibilities does not require treating a year as a guarantee. Skepticism need not become a prior verdict that something can never be done.
Retaining dates, definitions, sources, and acceptance criteria helps us know which judgment to revise when new results appear. That lets discussion accumulate more than repeatedly announcing a fulfilled prophecy.
Materials and revision scope: Revised November 4, 2026. Necessary background and forecast passages in Sequoia’s official AI Ascent 2025 transcript, and the research-intern definition, company-reporting status, and human-responsibility limits in OpenAI’s September 6, 2026 research-acceleration article were directly checked. This is not a repeated evaluation or independent capability certification. The event’s month and day were not verified; another overlapping outlook was not added as a source. Unverified five-level classifications, exact success rates, versions and retirements, investment capacity, hearing follow-through, and Middle East figures were removed. Future researcher goals are not republished as completed autonomous science. The tool scenario is hypothetical and the questions are the author’s suggestions; no new model, research, or geopolitical investigation was conducted.

💬 Comments
Loading...