This article is continuously updated with the latest developments in the conflict timeline and oil price data. The most recent update date appears in the “Last Updated” field above.
TL;DR. I wanted to understand where the US-Iran war is heading, so I had the AI agents at my disposal cross-check each other and obtained verifiable bilateral financial data. My assessment: this is an attrition war running on two clocks. Iran’s bankruptcy clock is ticking faster, but the US is also being chased by elections, oil prices, and interceptor stockpile constraints. The method (three-tier workflow plus a verification prompt generator) and all sources are in this article.
This morning I spent a long time chasing international news through Grok. With each exchange, a new column of citations appeared beside the response: 30 sources, 42 sources, 55 sources. But when I asked it to consolidate twenty-odd rounds of conversation into a single report, the sources section collapsed into one line:
Sources: Public news reports, official statements, historical case references
Zero links. Zero article titles. Zero dates. The hundreds of sources that had been visible moments before did not make it into the final report. Not one of them.
I was tracking this US-Iran conflict not simply to test AI. What I genuinely wanted to know was: where is this war going? To make that call, the intelligence I was working with had to be verifiable.
The first half of this article breaks down how three agents can divide the labor and where errors are most likely to enter. The second half uses verified financial data to offer my assessment of where the conflict is headed. This piece is part of the AI and Human Order series.
Three Tiers: Who Does What
The conclusion first. Multi-agent verification is not about throwing the same question at several models and finding the intersection of their answers. What actually works is separating three fundamentally different kinds of work:
| Tier | Task | Capability Required | Result in This Test |
|---|---|---|---|
| Retrieval | Surface the facts: broad, fresh, multi-source | Live web search, iterative follow-up | Data was mostly accurate |
| Synthesis | Collapse conversation into structured output | Long-form organization | All three models made errors here |
| Verification | Confirm each claim can be traced to its original source | Strong reasoning + actually opening links | Caught three hard errors |
The key point: synthesis and verification must be handled by different roles. The verification agent must not read the previous tier’s reasoning first, or it will simply follow the same narrative thread. The three tiers do not require three different brands of model. You can run three independent conversations inside the same AI: the first retrieves, the second synthesizes, the third sees only the finished output and verifies it claim by claim. What matters is not how many models you use, but that the three roles are never mixed together.
Tier One: Retrieval, Actually More Reliable Than I Expected
The point of this test was not to prove Grok unreliable. For example, Grok noted that the Singapore-flagged container ship Ever Lovely was struck by a drone on June 25 off the coast of Oman, sustaining bridge damage with no casualties. This checks out in gCaptain’s full report.
The figure that Iran’s economic losses reached $144 billion, roughly 40% of its pre-war GDP, also was not fabricated. It comes from an FDD estimate. After dozens of rounds of follow-up, ship names, casualty figures, and price data could mostly be traced to specific sources. In this test, the retrieval tier performed better than I originally expected.
Key practice at this tier: choose a model with live search capability, such as Grok or Perplexity, then keep pressing. One question, one answer usually yields only the most surface-level summary of events. Asking about the other side’s position, whether numbers hold up, and whether alternative explanations exist is what opens the data up.
Tier Two: Synthesis, and Where AI Is Most Likely to Err
Problems appeared when I asked Grok to consolidate twenty-plus rounds of conversation into a report. I will call this process “compression” from here on. The report’s timeline began here:
June 17: The US and Iran signed a temporary ceasefire memorandum of understanding (MOU)
In fact, the war began on February 28, with the strait closing on March 4. There was a brief ceasefire in April, followed by renewed escalation of the blockade, before the MOU was signed on June 17. Grok’s report began directly from June 17, compressing nearly four months of prior events into background. This also stripped context from the numbers that followed. The $144 billion figure represents losses that accumulated from the start of hostilities on February 28, but without any account of the months of fighting and blockade that preceded the MOU, readers have little basis for understanding how that loss was built up. The report also omitted the MOU’s core terms: the strait would remain open for free passage for 60 days, with management rights to be renegotiated at expiration. The real dispute is buried in that vague language.
More telling than what was omitted was how the original hedging disappeared during synthesis. When I asked Grok who violated the ceasefire first, it said:
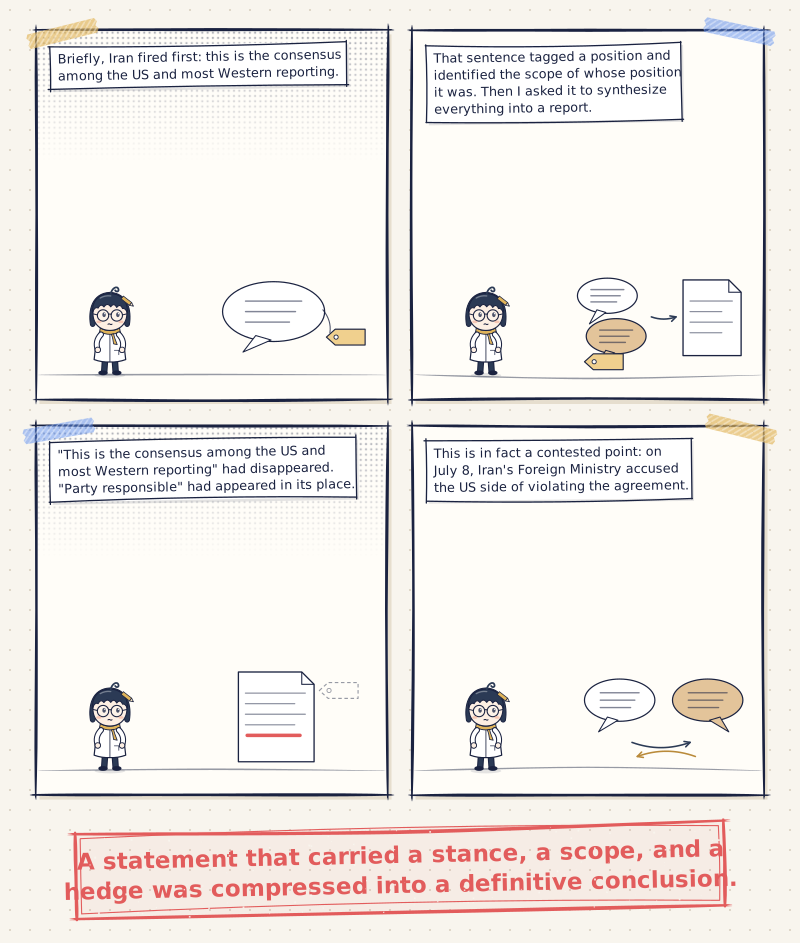
Briefly, Iran fired first: this is the consensus among the US and most Western reporting.
That sentence tagged a position and identified the scope of whose position it was. I followed up asking for Iran’s account, and it provided the IRGC’s version. Then I asked it to synthesize everything into a report. Section five read:
Conclusion: Iran fired first and is the party responsible for breaking the ceasefire agreement.
“This is the consensus among the US and most Western reporting” had disappeared. “Party responsible” had appeared in its place. This is in fact a contested point: on July 8, Iran’s Foreign Ministry accused the US side of violating the agreement. We typically think of AI hallucination as a model fabricating information from nothing. What happened here was different: conditions vanished. A statement that carried a stance, a scope, and a hedge was compressed into a definitive conclusion. The underlying facts were real, but the synthesis stripped out the original hedging. This kind of error is harder to spot than fabrication. Fabrication usually lacks a source and triggers suspicion; when hedging disappears, the event itself is still traceable, and readers may simply let it through.
I then passed Grok’s report to Perplexity for re-synthesis. It restored a good deal of important structure: a complete timeline, the 60-day free-passage clause, Bruegel’s analysis of who actually bears the transit fee burden, the UNCLOS legal dispute, and IEA estimates of alternative pipeline capacity. Crucially, all of these came with traceable links. Perplexity also found that Grok had underestimated annual transit fee revenue by nearly five times.
Finally, I handed both documents to Claude to write an initial draft. It also made errors, and made three of them. The draft identified two errors in Perplexity; on verification, neither charge held up. The first was not a wrong number but a missing date. Perplexity had written that “Brent has risen more than 45%, an increase of roughly $35 to $40,” and Claude concluded it had misrepresented a previous peak as the current price. Returning to the source revealed that this was a figure from Bruegel’s April 8 original text. The actual problem was that Perplexity had not preserved the data date. The draft also claimed that Perplexity’s “August 21 expiration date” was unverifiable. That date is verifiable: OFAC issued General License X on June 22, authorizing Iranian oil sales for 60 days through August 21. Perplexity had simply joined two genuine, 60-day windows that started from different dates.
The third problem was more direct. In a chart below, the draft labeled the July 7 oil price as “approximately $73.” The source text says July 8 and $76.48. The figure 73 appears nowhere, and the date is off by a day.
| Tier | Error | Nature |
|---|---|---|
| Grok | “Consensus among most Western reporting” became “conclusion” | Stripped stance and hedging language |
| Perplexity | Bruegel’s April figures presented as the current July situation; OFAC’s Aug. 21 date attached to the MOU’s clock | Dropped timestamps |
| Claude | Declared a verifiable date “unverifiable”; inserted an unsourced price point | Drew conclusions without verifying |
Three models, three different failure modes, all pointing to the same breakdown: synthesis. When a model compresses multiple rounds of conversation and multiple sources into one fluent report, source dates, the stance behind claims, applicability, and hedging language are the most likely casualties. In the original text, these are often brief parenthetical phrases. They carry enormous weight for assessing credibility, but in the drive for concision and fluency, they are typically the first to go.
Key practice at this tier: every time you pass material to the next agent, make sure three things travel with it: sources, timestamps, and hedging language. Without any one of them, the next tier has very little to work with when trying to trace back to the original.
This test also changed my view of Perplexity. I had initially assumed it could be skipped in a multi-agent workflow. This test showed me its value: even when it made synthesis errors, it preserved sources, which meant I could trace back to the original. By contrast, Grok’s report included a figure of “$430 million in daily losses” with no traceable source attached. I still cannot confirm where that number originated.
Tier Three: Verification. Four Instructions
When I first read the draft, I did not catch a single problem. The piece was well-structured, confidently written, and read so smoothly that I almost published it. But the byline is mine, and so is the responsibility for any errors.
What finally caught these problems was a fourth agent. It had not read any of the prior conversation or reasoning. It received only the finished output and operated as an independent verifier. The difference between it and the earlier models was simple: it actually opened the links, one by one. I gave it four instructions, and the third one did most of the work.
One: the verification tier must be independent. The verification agent can only receive the finished output. Do not let it read the prior reasoning, or it will follow the same line and end up endorsing the draft. If your tool supports sub-agents, open a separate independent agent. If you are working in a chat interface, open a fresh window, paste in only the finished output, and leave out all prior reasoning.
Two: report problems only, do not revise. When checking and rewriting happen simultaneously, it becomes very hard to know exactly where and how many errors the original contained. Produce a complete list of issues first; then a human decides what to change.
Three: actually open each source, do not rely on memory to restate it. The date and price errors in this case were caught because the verification agent actually opened the Bruegel PDF and the OFAC notice and compared them line by line against the draft. If the agent had been allowed to rely only on its existing knowledge or search summaries, these errors would almost certainly have passed through.
Four: explicitly tell it: “finding problems matters more than letting me pass.” Otherwise, the model will easily interpret its task as helping you finish an article rather than catching as many errors as possible.
Cross-Verification Prompt Generator
Select your scenario, copy the prompt, and paste it into whichever AI you prefer. Fill in the blanks with whatever you need verified.
The backbone of this prompt comes from the test documented in this article: it caught three hard errors. The single most effective instruction is the one requiring sources to be opened and read. Disable it and effectiveness drops sharply.
Once you have the report, do not accept it wholesale. Sort findings into four categories:
confirmed: supported by a reliable source; keep as is.corrected: a specific source proves the original was wrong; revise accordingly.unverifiable: cannot be confirmed at this time; delete it, add a source, or rephrase with more conservative language.overreach: the underlying fact is solid, but the inference exceeds what the evidence can support; narrow the wording.
One more safeguard: the verification agent itself can be wrong. Every item it flags as an error in the original still requires a human to open the source and confirm. In this case, the agent had one entry based on its own calculation and proactively labeled it “this is my own calculation, not a verified fact.” The real thing to watch for is when a calculation is written as though it were an already-verified fact. If you use Claude Code or Cowork, I have packaged this workflow as an installable skill: once installed, saying “please verify this” runs the full process. If you use a standard chat interface, copying the prompt above gives you roughly equivalent results.
The Intelligence Only Became Usable After Verification
Once retrieval, synthesis, and verification were complete, the conflict’s timeline and price movements became clear enough to work with. The price line in the chart below uses EIA official daily data; only event nodes that survived verification and can be traced to a source are included. Click any node to see details and attribution.
The most severe market disruption ran from March through April: passage through the strait was substantially impeded, and Brent climbed from roughly $72 to $126. When the agreement was announced on June 15, the price fell as much as 5.7% in a single day. The September futures contract settled at $84.95 on July 15, reflecting the market’s assessment that conflict had re-intensified but the strait had not returned to full closure.
Several dates are worth watching. The MOU’s free-passage window expires August 16. The OFAC waiver was originally set to run through August 21 but was revoked early on July 7, with a wind-down period ending July 17. The strait has been closed again since July 11, with the US resuming blockade operations. Trump abandoned the 20% transit fee proposal on July 14, one day after floating it.
This chart was not generated by a single model in a single pass. The price line connects to the EIA’s official spot price series; the event anchors are the version that survived retrieval, synthesis, and verification. Its most important feature has not changed: every event can be traced back to a specific source, and the price layer now is the source.
So Where Is This War Going?
Based on currently verifiable financial data, this is an economic attrition war, and it is a race between two clocks. Iran’s clock is ticking faster, but America’s clock is also counting down.
The three-tier workflow above was not a model comparison exercise. It was the means of obtaining numbers that can actually bear the weight of a judgment.
Iran’s ledger. Before the war, Iran was exporting slightly above 2.1 million barrels of oil per day; exports fell close to zero in May. FDD estimates daily losses during the blockade at roughly $435 million, with total losses since the start of hostilities near $144 billion, approaching 40% of pre-war GDP. The authors explicitly state this is a floor, not a ceiling. Official year-on-year inflation reached 88.6%, with meat prices near 178%. The rial has lost roughly 53% of its value over the past year. Per a CIA assessment reported by the Washington Post (via Iran International), Iran “can hold out for at least three to four months.” Economists within the system say that if the blockade extends beyond two or three months, the damage accelerates rapidly.
During the 26 days of ceasefire, Iran sold more than 80 million barrels of oil, taking in over $6 billion and briefly winding the clock back. But after July 17, even that legal window for oil sales closed.
What to read in the ship-count chart versus the oil price chart. Oil prices reflect market sentiment; ship counts reflect the strait’s physical reality. Oil prices move in response to OPEC, inventories, the Federal Reserve, and other factors unrelated to the strait. Ship counts do not. When the two lines diverge, the market is usually frightening itself.
Data source: IMF PortWatch (IMF × University of Oxford), satellite AIS statistics. Use the ArcGIS open endpoint at Daily_Chokepoints_Data/FeatureServer/0/query with portid=‘chokepoint6’ for Hormuz. Free, no API key required (verified July 16, 2026). Filter upstream using a where clause rather than pulling the entire dataset; outFields should be limited to date, n_tanker, n_cargo, and n_total, keeping tanker and cargo counts separate.
Start date: February 20, 2026, one week before the war began. Without a baseline period, there is no reference point for how far counts have fallen. A line without context is just a series of numbers.
Update frequency: daily pulls, but data lags four to seven days. This is daily granularity, not real-time. That distinction must be visible in the UI: the data_through field should record the actual cutoff date of the data, not the date of retrieval. Writing “real-time” is a lie; writing “updated daily” is also misleading. The only honest label is “data through [date].”
Validation is more important than retrieval. The upstream source can break in many ways:
- MIN_ROWS = 100: as of February 20, there are 140+ rows and counting. A return far below this number signals upstream truncation; fail immediately, do not write incomplete data.
- exceededTransferLimit: ArcGIS has per-query limits. Hitting them produces an error; don’t let the tail silently go missing.
- toISODate handles both epoch milliseconds and strings: ArcGIS date fields return different types depending on service configuration.
- Validate Number.isInteger and non-negative on every row; dirty data should not enter.
- Write to a temp file then renameSync: atomic write, no partial files.
- Any failure exits non-zero and does not overwrite the existing JSON.
One note: better to show old data with a clear date than to show bad data. If the data has not changed, leave the file completely untouched; the cron job can use git diff to decide whether to commit.
There is also a limitation more significant than latency: AIS is a signal ships broadcast themselves. Turn it off and you disappear from the data. Iran’s accusation against the Mombasa and Al Bahiyah cited their disabling of identification systems. The more intense the conflict, the more likely ships are to turn off AIS, and the more this chart undercounts actual traffic.
What this chart measures is not “how many ships transited.” It is “how many ships transited while publicly broadcasting that they were doing so.” That is the epistemological boundary of this data.
When someone says “the strait has returned to normal,” we now have an IMF line to check that against.
America’s ledger. Official figures through the end of June show roughly $30 billion spent; CSIS estimates $34–42 billion, with munitions at $26.1 billion as the largest single item. The absolute figures are not small, and the unit economics are worse: one interceptor missile costs dozens of times more than the drone it shoots down. As a rough GDP comparison, the US has spent about 0.15% of GDP in direct military costs; Iran’s total economic losses approach 40% of its pre-war GDP. The two figures are not perfectly comparable in scope, but the gap in staying power is visible. The question is not who is spending less, but who can afford to keep spending.
Iran’s military spending is a black box; the following is inference, not verification. No think tank has published a dollar estimate for Iranian munitions consumption. Iran is reported to have fired roughly 1,500 to 2,300 ballistic missiles (INSS, NBC/IDF, and JINSA figures vary) and approximately 4,400 to 5,400 kamikaze drones (including proxy launches, depending on how the count is defined). Using publicly available unit cost ranges as a rough estimate, combat consumption comes to perhaps $1–5 billion, roughly one-tenth of the US direct military bill. This is the logic of cheap attrition warfare: force an opponent to burn expensive interceptors at a fraction of the cost.
But Iran carries another, larger ledger: destroyed military assets. FDD estimates replacement costs at roughly $46 billion, about half of FDD’s total physical replacement estimate of $91 billion, equivalent to four to six years of Iran’s annual defense budget (SIPRI puts the annual figure at roughly $7.4 billion). Adding munitions consumption to destroyed military assets, the two sides’ military bills may be in a similar order of magnitude. The nature of the costs is entirely different, though: what the US is burning through is cash flow that can be replenished through budgeting and production. What Iran has lost is a capital stock it cannot rebuild quickly.
The US, however, has three clocks of its own.
First: interceptor stockpiles. Seven weeks of operations consumed nearly half of Patriot inventory and at least half of THAAD. No new THAAD deliveries are scheduled for 2026, and replenishment is not expected until 2027.
Second: midterm elections. 58% of Americans oppose this war. Gasoline rose from $2.98 to $4.48 per gallon by mid-May. The war bill arrives directly in voters’ mailboxes.
Third: the buffer room on oil prices. The Strategic Petroleum Reserve has fallen to its lowest level since 1983, leaving the US with fewer policy tools for suppressing oil prices than it has had in decades.
American behavior lines up with all three of these clocks: three attempts at a ceasefire within four months, and a transit fee proposal floated on July 13 and abandoned within a day.
My conclusion, then: the United States can absorb the costs of this war far more easily than Iran, and a blockade-based economic attrition strategy is viable for it. The longer the conflict drags on, the worse it is for Iran. But time is not entirely on America’s side. This is a race between Iran’s bankruptcy clock and America’s clocks for elections, oil prices, and interceptor resupply. Whichever clock strikes first is likely where the war turns.
This assessment has a boundary: it rests on verifiable public data available in mid-July, and several key numbers remain unavailable today. How much usable foreign exchange Iran still holds, the additional US expenditure since hostilities resumed on July 8, and Iran’s July inflation figures all lack reliable numbers. Any one of those filling in could require a revision. That is exactly why the method in the first half of this article exists: a judgment is not the end of the process. The judgment rests on the data. When the data changes, it must change too.
Three Questions Worth Asking
Beyond tools and workflow, what raised the quality of verification was three questions I kept returning to in conversation. None of them require a paid subscription. When I asked “what does Iran’s side say?” Grok provided the IRGC’s version. When I asked “does this casualty figure make sense?” it checked crew sizes and the location of the strike. When I asked “could this have been staged?” it began actively testing the alternative hypothesis.
Condensed to their simplest form, the three questions are: What does the other side say? Does this number hold up? Could this be something other than what it appears to be?
Models do not typically raise these questions on their own. If you do not push, the model will usually keep answering within the narrative that formed in the previous round. These three questions are the substance of “keep pressing” at the retrieval tier.
I wrote in an earlier piece, Knowledge Management Without Discipline, Through Pipelines, that any process relying on sustained human manual maintenance tends to break down over time. The context then was note-taking. Applying the same idea to fact-checking, I realize that conclusion was only half right. A pipeline can transport data, preserve sources, even automatically dispatch an agent to open links one by one. But whether to run it at all still requires someone to make a decision.
This morning I nearly did not.
When Anyone Can Quickly Brief Themselves on a Global Crisis, What Comes Next?
The tools are genuinely here. Running the three-tier workflow over one morning gave me a quantity of data and breadth of analysis that would have taken a journalist in the mid-2010s a database subscription, several think tank contacts, and multiple interviews to produce as preliminary research. The barrier to accessing information has fallen to a remarkable low.
The barrier to entry that remains is the willingness to ask one more question: where does this number come from?
Stacking more AI on top of existing AI does not answer that question automatically. If every tier only rewrites the conclusion of the previous one, errors become more fluent, more structured, and more closely resemble a polished report ready to send. The last line of Grok’s report read: “This report is for reference only and does not constitute investment or decision-making advice.” It has learned to write a disclaimer. It just has not learned to bring the sources along.
The verification tool above is the safeguard I built for myself today. Every important article from now on will go through it first. You are welcome to use it directly.
Frequently Asked Questions
Q: How should the labor be divided in a multi-agent verification workflow?
Three tiers. The retrieval tier needs breadth and freshness, so use a model with live web search and keep pressing the same question rather than asking once and stopping. The synthesis tier collapses conversation into structure; this is where errors most often occur, and when handing off, sources, timestamps, and hedging language must all travel with the content. The verification tier must be handled by an independent agent that has not read the prior reasoning; it receives only the finished output, with instructions to report only and not revise, and must actually open each link to return to the original source.
Q: Do I need three separate AI subscriptions?
No. The three tiers do not have to be handled by three different brands of model. You can run three independent conversations inside the same AI: the first retrieves information, the second synthesizes it, the third sees only the finished output and verifies it claim by claim. What matters is not how many models you use, but that the three roles are kept separate.
Q: Which numbers in the Grok report were actually accurate?
Ship names, dates, and casualty figures were mostly correct: the Ever Lovely was struck by a drone on June 25, the Mombasa and Al Bahiyah by cruise missiles on July 13, with 1 dead and 8 injured (6 Indian nationals, 2 Ukrainian nationals, 4 critically injured), each verifiable. The $144 billion figure was not fabricated either; it comes from an FDD estimate. But FDD’s actual range was $50–300 billion, with $144 billion as the most likely value. The report treated it as a definitive number.
Q: Can this be done without paid subscriptions?
Yes. The main cost is patience. A single model can run this workflow; you just have to play the role of the verification tier yourself: open a brand-new conversation window, paste in the finished output without any prior reasoning, and run the four instructions. The two moves that actually matter are asking what the other side says and opening the source to look at it yourself.
Want to Build a Chart Like This? Hand This Block to Claude Code or Another AI Coding Tool
The retrieval pipeline behind the Hormuz strait ship-count chart above can be copied wholesale into any AI coding tool (Claude Code, Codex, or similar). Swap in a chokepoint or port you care about:
I want to build a daily-transit-volume data pipeline. The source is the IMF PortWatch
(IMF × University of Oxford, satellite AIS statistics) public ArcGIS endpoint,
no API key required.

Endpoint:
https://services9.arcgis.com/weJ1QsnbMYJlCHdG/arcgis/rest/services/Daily_Chokepoints_Data/FeatureServer/0/query

I want to look at "{the strait or chokepoint I care about}". Please first look up
the portid code mapping for this layer; do not guess; check the official IMF PortWatch
page at https://portwatch.imf.org/ or query the endpoint with no where condition
to see what distinct portid values exist, then list them for me to confirm before
proceeding.

Retrieval rules:
- Apply the where condition upstream (portid + start date), do not pull the full
  dataset and filter locally.
- outFields should include only the necessary columns (date, vessel type breakdown,
  total count); do not pull everything.
- Set the start date to roughly one week before the event I care about, to establish
  a pre-event baseline. Without that baseline the line has no reference and anomalies
  are invisible.
- There is a known publication lag (PortWatch is roughly 4–7 days behind). Record
  this as a data_through field: the actual cutoff date of the data, not the
  retrieval date. The UI copy must say "data through [date]" only. "Real-time"
  is false; "updated daily" is also misleading.

Validation rules (these matter more than the retrieval logic itself):
1. Set a MIN_ROWS floor (estimate the minimum expected row count from the start date
   to today). If the return is well below that number, treat it as upstream truncation:
   exit non-zero, do not write the incomplete data to file.
2. Check whether the response includes an exceededTransferLimit field. If it does,
   the service has paginated; handle pagination or throw an error; do not silently
   lose the tail.
3. Handle the date field as both epoch milliseconds and as a string, because ArcGIS
   service configurations return different types.
4. Validate every row's value as a non-negative integer; reject dirty data.
5. Write to a temp file first, then rename into place (atomic write). Do not
   overwrite the existing file in place; a mid-run interruption must not leave a
   partial file.
6. Any failure exits non-zero and does not overwrite the existing valid JSON.
   Show stale data with a clear date rather than bad data.
7. If the newly retrieved data is identical to the previous version, do not touch
   the file at all. This lets downstream automation (e.g. a cron job checking
   git diff) decide whether to commit, and avoids meaningless noise commits.

Finally, help me think through the blind spots in this data. (Hint: AIS is a
signal ships broadcast voluntarily. Switch it off and you vanish from the dataset.
The more dangerous the conflict zone, the more this method is likely to undercount
actual traffic.) State this clearly so that readers do not mistake the chart for
"the absolute truth about ship positions."
This prompt is deliberately written to say “look up the portid mapping first, do not guess,” because chokepoint6 is the Hormuz code we have already verified through live testing. Other straits (Malacca, Suez, Panama) may use different codes. Copying blindly risks querying the wrong location; having the AI verify against the source first is the safer approach.
Brent Crude × US-Iran Conflict Timeline
February 27, 2026 to October 20, 2026. Brent spot prices, with data through October 20, 2026 (EIA, roughly a one-week publication lag). Click any node for event details and sources.
The price line is the EIA daily Brent spot series, with its cutoff date noted above. The diamond anchors are hand-curated events, each with its original source attached. Prices shown on the anchors come from the spot series and will differ from the futures or intraday prices cited in the event text: both are correct, they are simply different series.
Daily Vessel Transits Through the Strait of Hormuz
February 20, 2026 to October 25, 2026. Data through October 25, 2026 (IMF PortWatch satellite AIS counts, roughly a 4-to-7-day publication lag). Drag the timeline or press play.
Coastlines and shipping lanes are hand-drawn approximations, not a precise nautical chart. The number of ship dots is proportional to that day's transit count (IMF PortWatch); they are not live vessel positions. Gold marks tankers, ink marks other merchant ships; diamond markers show the approximate locations of vessel attacks, each lighting up when the timeline reaches that day. Pre-war (February 20 to 27), an average of 97 vessels passed through per day (a different counting method from the roughly 138/day JMIC figure cited in the article).
💬 Comments
Loading...