When AI explains its limitations clearly, can we simply trust that self-introduction?
The original article organized my conversation with Gemini about language, truth, and lies. It raised more than the question of whether an answer is correct: how does a fluent system earn our trust?
This revision retains that question without allowing statements within the conversation to establish the model’s internal mechanisms. Inspiring reflection and proving an engineering fact are different uses.
TL;DR: Generative AI may confidently produce incorrect content, but a gap in information does not necessarily force fabrication, models can also acknowledge uncertainty or decline requests. Self-description alone cannot establish understanding, knowledge, or intention. This essay treats the original conversation as a historical summary and author reflection without filling missing records. Risk guidance and a developer report correct absolute claims, followed by an approach to allocating trust according to tasks, evidence, and consequences.
1. First clarify what this conversation can establish
The original article already summarized some answers as their gist, rather than providing a complete verbatim transcript. This revision likewise has no original chat, precise model version, system settings, or record of tool use.
The wave metaphor, lying without intention, and functional trust mentioned in the original remain ideas prompted by that summary. They are not repackaged as Gemini’s verbatim testimony, and I do not add a new conversation to fill the gaps.
Model statements such as “I do not understand” or “I have no intention” are still outputs. They can begin an inquiry, but cannot alone establish the system’s mechanisms or a philosophical mental state.
This is not a controlled experiment, does not compare the honesty of Gemini, ChatGPT, or other models, and does not claim to reproduce the 2025 interaction.
2. Predicting language does not directly imply a complete absence of understanding
Describing a language model as predicting what comes next can help explain generation. But a training objective and the question of understanding cannot be equated in one sentence.
I no longer infer from statistical prediction that the model knows no facts. Nor do I reduce generation to choosing the most probable word every time, or imagine an empty database that can only guess. Correctness and error both require examining particular outputs and checkable information.
NIST’s 2024 generative AI risk profile notes that statistical prediction can produce accurate, consistent content as well as inaccurate or internally inconsistent content.[1] This supports checking answers, not declaring every answer wrong.
As for the conditions of understanding, knowledge, and intention, this essay offers no experiment that settles the philosophical debate. Waves are a metaphor, not a system architecture diagram.
3. Hallucination is a risk, not an inevitable outcome of every question
NIST describes confabulation as confidently presenting erroneous or false content and cautions that fabricated reasoning and citations can increase inappropriate trust.[1] That is the problem I want readers to notice.
But the original claims that an algorithm forces an answer, never says “I don’t know,” and always sounds confident were too absolute. I withdraw them. The existence of error risk does not mean that every information gap must lead to fabrication.
Google’s Gemini 2.5 technical report v1 describes post-training, tool use, safety policies, and refusal-related design.[2] This developer account of a particular 2025 model family gives us reason not to treat every behavior as an inevitable consequence of a single prediction rule. It is not an independent reliability evaluation conducted here and cannot reconstruct the original conversation’s settings.
I would focus on results: what is supported, what remains unconfirmed, and how an error can be found and corrected. If calling it “structural dishonesty” conceals those distinctions, the label itself needs reconsideration.
4. Question authoritative tone without inventing a verdict on human nature
A confident answer might make me ask “Where is the evidence?” one fewer time. That is a risk I want to remind myself about, not a psychological survey completed in this essay.
The original attributed trust in confident speakers to evolutionary instinct and claimed that intelligent people were more vulnerable than anyone else. It supplied insufficient evidence for those comparisons, which I no longer retain as general conclusions.
Nor do I assume that every reader stops thinking, or that only a minority can ever remain alert. A more useful question is how much checking I am willing to do for a particular task, and whom an error would affect.
Skepticism need not reject everything. It can mean extracting important figures, quotations, and causal claims from a fluent narrative and looking for their basis separately.
5. Bring functional trust back to assessable work
I still want to use “functional trust” for conditional collaboration: rather than first trusting an entire system, specify how this task will be accepted. Here it is a working concept I adopt, not a claim that the original conversation’s verbatim attribution has been verified.
For example, ask AI to organize material you provide, then check for omissions or changes of meaning. If adopting a new figure, return to its corresponding source. These are illustrative practices, not accuracy tests completed in this essay.
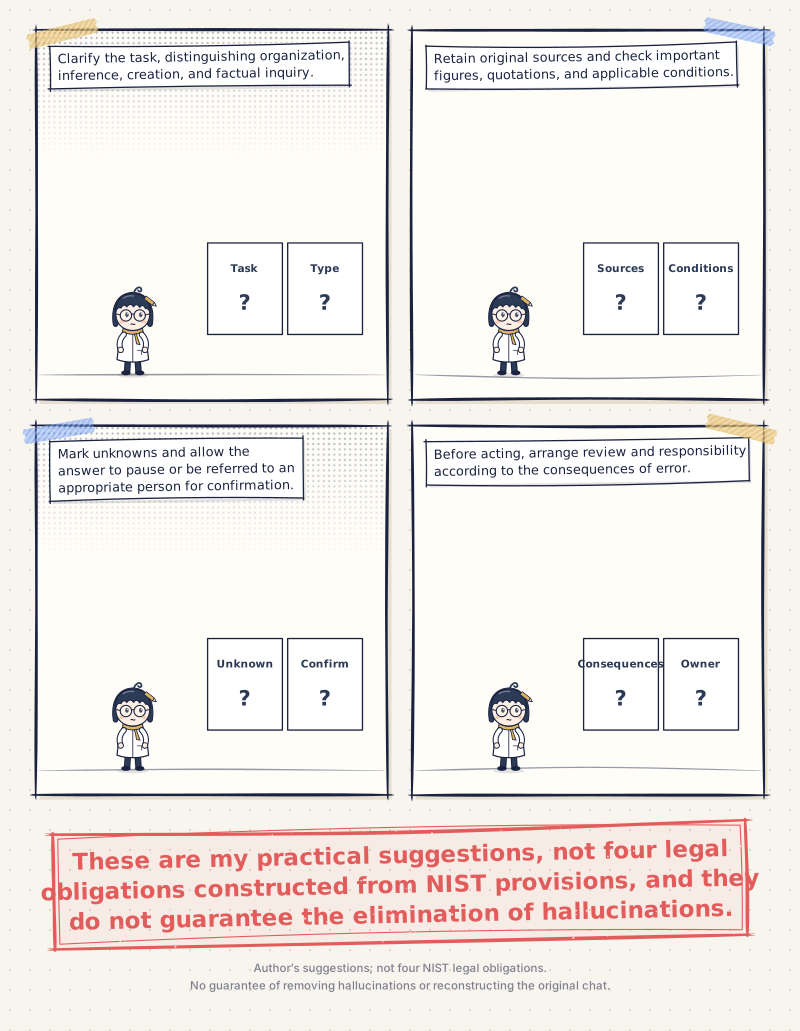
I would begin with four checks:
- Clarify the task, distinguishing organization, inference, creation, and factual inquiry.
- Retain original sources and check important figures, quotations, and applicable conditions.
- Mark unknowns and allow the answer to pause or be referred to an appropriate person for confirmation.
- Before acting, arrange review and responsibility according to the consequences of error.
These are my practical suggestions, not four legal obligations constructed from NIST provisions, and they do not guarantee the elimination of hallucinations.
6. Trust can be bounded, and checking can be learned
The original said skills could be taught but literacy could only grow by itself, and that those willing to practice would forever remain a minority. I have no evidence for judging everyone’s learning ability that way, and withdraw those claims.
I would take a more concrete direction: build source checks, identified inferences, and explicit uncertainty into repeated work. Success still depends on circumstances and resources; saying “stay alert” does not accomplish the task.
Faith’s reminder of limited knowledge inspires me. But this is my analogy, not proof that theology and model engineering face the same epistemic problem. A tool need not become omniscient before it is useful.
The trust I want to retain means knowing what I delegate this time, while keeping ways to inspect and correct it. Between making an answer sound true and having enough reason to adopt it, there should remain a checkable distance.
Sources and scope of reading (checked through November 4, 2026)
- NIST AI 600-1, Generative Artificial Intelligence Profile, July 2024: Section 2.2, PDF page 10, on confabulation, accurate and inaccurate outputs, and inappropriate trust. A risk-management document, not a philosophical verdict on intention or understanding, and not a statement of current 2026 policy.
- Google Gemini Team, Gemini 2.5 technical report v1, July 7, 2025: Section 2 on post-training and tool use and Section 5 on safety and refusals. A developer report, not an independent reliability test, a 2026 model ranking, or a reconstruction of the original conversation’s version and settings.

💬 Comments
Loading...