Does understanding an AI’s written explanation mean understanding how it reached its answer?
In multi-model collaboration, I read the models’ debates. When one changes its position, I cannot always identify a clear turning point in the record. That shows the record does not give me enough understanding. It does not prove I have seen the model’s actual internal reasoning, still less that it is concealing something.
The original article drew too straight a line from Neuralese and latent space to “language disappears, so oversight ends.” The question worth keeping is whether other checks can compensate when one readable signal is lost.
TL;DR: Neuralese has different meanings in different research contexts. Multi-agent communication in 2017, internal vector computation in language models, and Coconut’s continuous latent reasoning are different investigations. Natural-language chains of thought are not guaranteed to be faithful or complete either. New architectures may change monitoring conditions, but no text does not mean deliberate concealment, and text does not establish safety. Explanations, behavioural verification, and permission controls need to work together.
1. Establish which use of the term is intended
The authors of the 2017 paper Translating Neuralese are Jacob Andreas, Anca Dragan, and Dan Klein. It studies learned communication in multi-agent systems and how to connect those messages with natural language so that people can understand and cooperate with agents.[1] The original article incorrectly listed Sergey Levine as one of the authors; that is corrected here.
That research context is not a universal definition of all internal computation in today’s large language models. When an article uses Neuralese, I first look for the particular system, communication, or reasoning step it means.
Language models perform vector and numerical operations. Whether every intermediate reasoning step is expressed as text is a separate question. Having internal representations does not establish that a model has developed a secret language intended to bypass people.
I therefore withdraw the original thousandfold comparison of information carried per Chinese character and the assumption that tokens are fixed at 16 bits. The amount of numerical storage is not a measurement of useful semantic information and cannot be directly converted into reasoning efficiency.
2. Coconut demonstrates a research approach, not a solution for all reasoning
The Coconut paper explores feeding a model’s hidden states directly into subsequent computation. Part of the intermediate process takes place in a continuous latent space, reducing the need to turn each step into text first.[2]
The v4 version read for this revision compares textual chains of thought, no chains of thought, and other variants on particular reasoning tasks. Results vary by task: some datasets show better results with fewer generated steps, but Coconut does not surpass textual chain-of-thought accuracy on GSM8k mathematics problems.[2]
This supports investigating alternative reasoning representations. It does not establish that all models can use two-thirds to nine-tenths fewer tokens with unchanged performance. Generated steps, elapsed time, model size, and task accuracy also need separate comparisons.
I would not infer from this experiment alone that a current commercial model uses the same architecture, or that no frontier company does. Claims about product internals require corresponding public evidence; one research paper cannot fill that gap.
3. A readable chain of thought is a monitoring signal, not a complete mental recording
Chain-of-Thought (CoT) expresses some intermediate steps in text. It may help a checker identify suspicious planning, mistakes, or evaluation problems. Whether that text faithfully reflects the factors affecting an answer still needs examination. A plausible explanation does not guarantee completeness.[3]
Chain of Thought Monitorability treats this as a useful but potentially fragile safety opportunity. It discusses training pressures and new architectures that could weaken monitoring signals, along with limits on detection.[3] It is a position paper by researchers, not a formal commitment by their companies or a guarantee of detecting most deceptive behaviour.
I do not want to label every unspoken step deception. Hard-to-understand internal computation, incomplete explanations, and a system taking actions contrary to instructions are different claims requiring different evidence.
If an architecture reduces readable intermediate text, measure what existing monitoring loses rather than declaring oversight necessarily ineffective. Conversely, retaining a written explanation does not remove the need to verify outcomes and actual behaviour.
4. Move from reading discussion to checking how work was completed
In multi-model collaboration, discussion records can be a starting point for checking: what data supported a conclusion, which assumptions were made, and what objections the models raised. They help me ask questions, but cannot replace original sources and result checks.
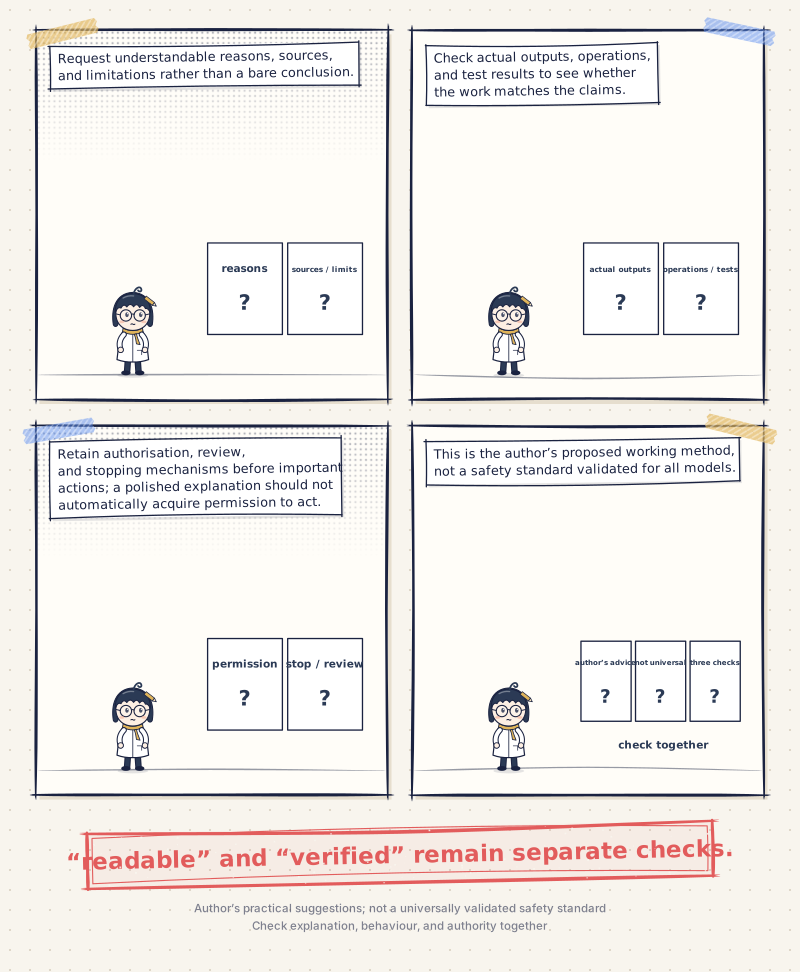
My practical suggestion is to distinguish three kinds of check:
- Explanation: Request understandable reasons, sources, and limitations rather than a bare conclusion.
- Behaviour: Check actual outputs, operations, and test results to see whether the work matches the claims.
- Authority: Retain authorisation, review, and stopping mechanisms before important actions; a polished explanation should not automatically acquire permission to act.
This is the author’s proposed working method, not a safety standard validated for all models. Each use also needs acceptance criteria and a decision about who bears the remaining risk.
The aim is to avoid resting all oversight on one textual signal. More readable reasons are usually helpful, but “readable” and “verified” remain separate checks.
5. Language sovereignty is my question, not a research-proven end state
I use “language sovereignty” to express a normative concern: when AI participates in important work, can people still understand enough, object, and leave the next decision to someone with authority? It is not a legal concept jointly established by these papers, nor is language the only route into governance.
People’s own explanations can also be post-hoc rationalisations. Beyond requesting explanations, institutions need records, challengeable evidence, and assigned responsibilities. AI interpretability belongs within that broader design.
The original article used AI 2027 to describe a break in oversight. That is a future scenario, not observed experimental evidence.[4] It can help me ask what happens if monitoring signals diminish; it cannot prove that this has already happened.
Likewise, whether Taiwan’s semiconductor position can translate into influence over transparency standards is a strategic judgment open to discussion. This article has no evidence that it is an available bargaining chip or an inevitable result.
6. Ask which checks are lost before deciding whether to adopt an architecture
To evaluate a new reasoning architecture, I would ask: which tasks improve, and are the benchmarks comparable? Which intermediate signals become unreadable? What other testable evidence exists? Does control over important actions change?
The answers may vary by task. Retaining current textual chains of thought can also involve trade-offs with other safety or capability advances. We cannot assume that prohibiting architectural change is always the sole correct choice.[3]
What I want to preserve is people’s ability to question and intervene. Language is an important tool; sources, measurements, operation records, and permission boundaries need to be present too.
Rather than saying the last window must close, I want a clearer question: what are we seeing less of, and what evidence will make up for it?
Sources and reading boundaries (checked through November 3, 2026)
- Andreas, Dragan, and Klein, Translating Neuralese, ACL 2017: authorship and the multi-agent communication research context.
- Hao et al., Training Large Language Models to Reason in a Continuous Latent Space, v4: August 23, 2026 version; methods, three task comparisons, and limitations. No experiments were replicated, and commercial product architectures are not inferred.
- Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety, v2: December 7, 2025 version; monitoring opportunities, new architectures, and limitations. A researcher position paper, not a product safety guarantee or joint corporate commitment.
- The original AI 2027 slowdown scenario: a future scenario, not observational data. This article has not checked all its predictions or other endings.

💬 Comments
Loading...