Have the articles I publish on paulkuo.tw entered an AI training dataset?
I worry about it, but I have no evidence that every article has been included. Crawling a website, retaining its content, adding it to training data, and later producing similar text are different events. A bot visit alone does not establish that entire chain.
TL;DR: To assess whether AI-related use of content is lawful, ask how the material was obtained, what it is used for, and how outputs are used, then examine the relevant jurisdictions. Japan, Singapore, and the EU attach different conditions to data-analysis exceptions; US fair use depends on the facts; Taiwan already has copyright rules. Creators can document rights and use, but technical controls, licence terms, and legal remedies each have limits.
1. Separate three stages of “AI used my work”
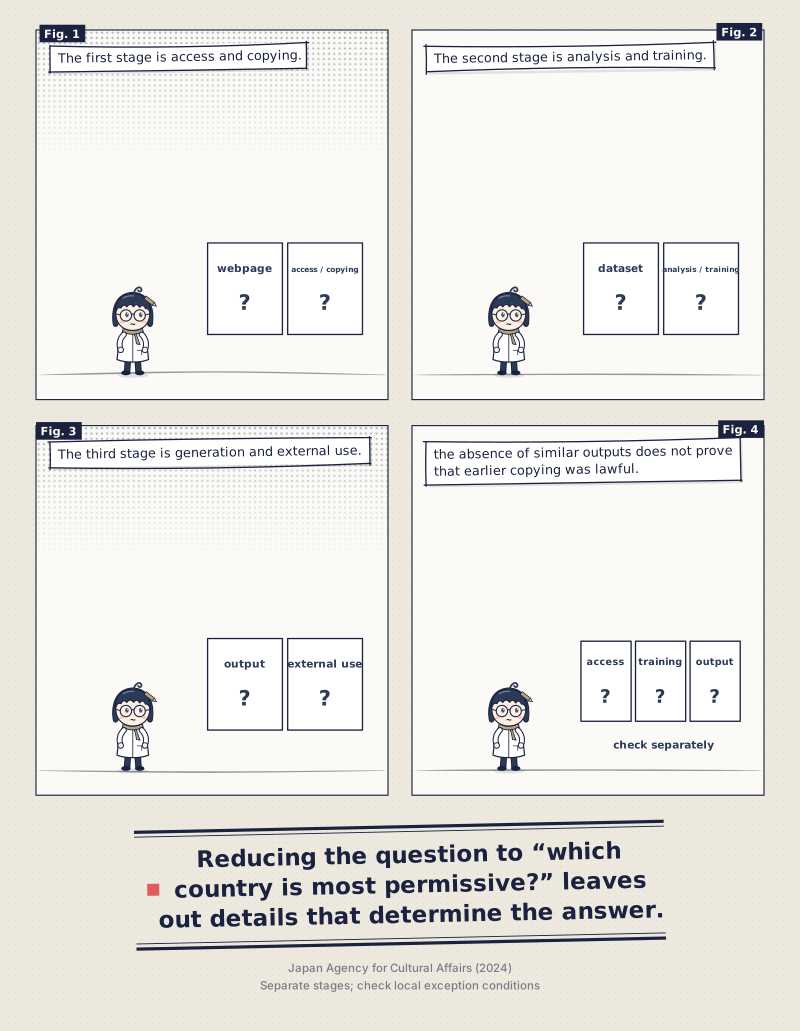
The first stage is access and copying. Reading webpages, downloading images, or building a dataset may involve reproduction. Public availability does not automatically permit unrestricted reuse. Protection, permission, and the method of access still matter.
The second stage is analysis and training. Text and data mining (TDM) uses automated methods to analyse digital content for patterns, trends, or correlations. Jurisdictions may provide exceptions for such purposes, but their conditions differ. Neither “research” nor “AI” is a universal pass.
The third stage is generation and external use. Even if an analysis qualifies for an exception, that does not establish that every output can be sold or published. Conversely, the absence of similar outputs does not prove that earlier copying was lawful. Japan’s Agency for Cultural Affairs explicitly distinguishes development and training from generation and use.[1]
This distinction is my starting point for reading national frameworks. Reducing the question to “which country is most permissive?” leaves out details that determine the answer.
2. Japan and Singapore: analysis exceptions with conditions
Japan’s Copyright Act Article 30-4 provides room for certain uses that are not intended to enjoy the thoughts or sentiments expressed in a work. AI development and data analysis may qualify. The Agency also explains that uses involving an enjoyment purpose, or unreasonably prejudicing a rightsholder’s interests, may fall outside it. Its 2024 explanatory document explicitly says it is not legally binding; it is not a judgment on a particular case.[1]
I therefore withdraw the earlier wording that any purpose is permitted. Commercial status is worth examining, but it is not the only condition.
Singapore’s Copyright Act 2021, sections 243 and 244, addresses computational data analysis, including using works to improve a computer program’s functioning. IPOS explains conditions including lawful access, limits on the purpose for which copies may be used, and restrictions on supplying copies to others.[2] This creates a basis for qualifying analysis; it does not mean access restrictions can be bypassed and downloaded works resold as a database.
The two frameworks can be compared without awarding first and second place for innovation. Businesses need to explain how the conditions apply to their actual data flows.
3. United States: fair use is more than transformativeness
The earlier article moved too quickly from Google Books to the proposition that generative AI training follows the same lawful route.
US fair use considers factors including the purpose and character of use, the nature of the work, the amount used, and market effects. A transformative purpose does not erase the other factors. The US Copyright Office’s May 2025 pre-publication report on AI training separately addresses data acquisition, training, retrieval-augmented generation, and outputs, and analyses different scenarios.[3]
The report is legal and policy analysis, not a ruling that every model is lawful. Individual litigation turns on works, acquisition methods, claims, and evidence. This article does not catalogue or claim to confirm the latest outcome of every case as of today.
“The model becomes parameters” describes part of a technical result. It cannot by itself establish whether preceding reproduction was permitted. I no longer label the United States uniformly the most permissive jurisdiction.
4. European Union and United Kingdom: identify who and what the exception covers
The EU’s 2019 Digital Single Market Copyright Directive establishes different TDM provisions. Article 3 concerns scientific research by qualifying research organisations and cultural heritage institutions. Article 4 provides a broader exception, with conditions including lawful access and whether rightsholders have appropriately reserved their rights.[4]
A rights reservation affects the Article 4 exception; it cannot simply be applied to all data analysis. Machine-readable reservations are particularly relevant to publicly available online content. Nor does reserving rights mean a switch can retrieve data from an existing model. The European Commission has also been discussing technical approaches to identifying and respecting TDM rights reservations, illustrating unresolved implementation questions.[5]
A UK government report published in March 2026 describes the existing section 29A data-analysis exception for non-commercial research, alongside other potentially relevant provisions and policy options.[6] Discussions, proposals, and enacted law must be distinguished. Discussion of a broader exception does not mean commercial training has already been universally authorised.
These are entry points to the frameworks, not a table that decides the applicable law for a cross-border project. Neither an author’s residence nor a company’s location alone resolves every legal question.
5. Taiwan: clearer guidance is needed, but existing law is not absent
Taiwan’s Intellectual Property Office directly addressed AI training in its August 29, 2025 explanation: collection, preprocessing, training, and optimisation may involve reproduction. Permission or licensing remains necessary unless fair use or another applicable basis allows the use, and courts determine individual cases on their facts.[7]
That differs considerably from saying Taiwanese law does not protect creators. The absence of a particular specialised exception is not the absence of existing rights. I still want practical guidance that developers and creators can understand, but that policy preference must not rewrite the current framework.
The earlier article also loosely called Lawsnote a 2024 AI-training judgment. The June 24, 2025 first-instance judgment examined here includes directly placing crawled legal-history content into a competing database. The court expressly distinguished that conduct from using material to train AI.[8] It cannot decide every crawler or model-training scenario. This article has not verified later appellate outcomes and does not present that first-instance ruling as final.
For me, the practical imbalance is that individual authors struggle to discover how their work travels and may lack resources to gather evidence case by case. That difficulty deserves discussion supported by accurate legal descriptions.
6. What records can creators start keeping?
I would first organise original files, publication dates, the rights I can license, and uses I wish to allow or restrict. If potentially unauthorised use appears, record URLs, dates, specific similar passages, and evidence available at the time. A professional familiar with the relevant jurisdiction can then assess a dispute when needed.
Websites can also configure crawler rules, access restrictions, or licence terms according to services’ published documentation. Their functions differ: crawler rules express requests to programs that honour them; they are not security controls that block every program. Restricting future access does not guarantee removal of earlier training results. Search indexing, live retrieval, and model training should not be treated as one setting.
For businesses building datasets, I suggest listing sources, acquisition methods, rights bases, purposes, retention, and provision to others. This is the author’s suggested starting point, not a form that grants a legal exemption.
I want my articles to be read and to retain a say in subsequent use. Explaining what technology, contracts, and law can each address makes it possible to formulate requests that can actually be acted upon.
Sources and limits of review (checked through November 3, 2026)
- Japan Agency for Cultural Affairs: overview of AI and copyright, May 2024, particularly pages 3 and 5–8; non-binding interpretation.
- Singapore IPOS: conditions for text mining and machine learning, relating to sections 243–244; no case-specific legal opinion is provided here.
- US Copyright Office: AI training report, May 2025 pre-publication version; official report index and version information.
- European Commission IP Helpdesk: TDM FAQs, distinguishing Articles 3 and 4. The original directive link encountered site verification; a complete article-by-article recheck is not claimed.
- European Commission: stakeholder consultation on AI and copyright compliance, on technical implementation of TDM rights reservations.
- UK government: Report on Copyright and Artificial Intelligence, March 2026.
- Taiwan TIPO: email interpretation 1140829; an administrative explanation, with courts determining individual disputes.
- Taiwan New Taipei District Court, criminal judgment 111 Zhi Su No. 8, June 24, 2025, cited only for the facts and distinction in that first-instance ruling; later proceedings are not verified.
This article compares frameworks and presents the author’s views. It is not case-specific legal advice.

💬 Comments
Loading...