Summary: Anthropic’s internal data can help us understand how AI participates in AI development. Reading the figures still requires us to distinguish code volume, session success rates, and autonomous research capability. This essay revisits the source’s historical observations while keeping the company’s reports, future scenarios, and my own judgments about work separate.
The phrase “AI is starting to build itself” easily suggests that a loop has already closed: one generation completes the next, which then improves itself again. But helping researchers write code is not the same stage as autonomously choosing a research direction and building a successor system.
That distinction is what I most wanted to preserve from Anthropic Institute’s “When AI builds itself,” written by Marina Favaro and Jack Clark and later updated. The figures below are limited to the historical observation periods explicitly identified in that article. They are not a report on the capabilities of every model today.
Separate Acceleration from Autonomy
The source argues that AI is already accelerating development work within the company. It also explicitly says that full recursive self-improvement has not been achieved and is not inevitable.
Starting from there, I want to separate several questions. Which steps can the tool execute? Who defines the goal? Who judges the result? Does a person still need to frame the problem again before the next round?
Participating in the development process is not the same as being able to build a successor system autonomously.
Compressing those questions into “AI can build AI” creates tension, but it hides the level at which the current evidence actually sits.
Eightfold: Which Quantity Increased?
In its detailed discussion, the source reports that in the second quarter of 2026, daily lines of code merged per engineer were about eight times the 2024 level. It also cautions that lines of code overweight volume and cannot be translated directly into an equivalent productivity increase. The article’s opening and figure captions use different time aggregation, so I use the definition in the detailed passage rather than mixing a quarterly description with a multiyear average.
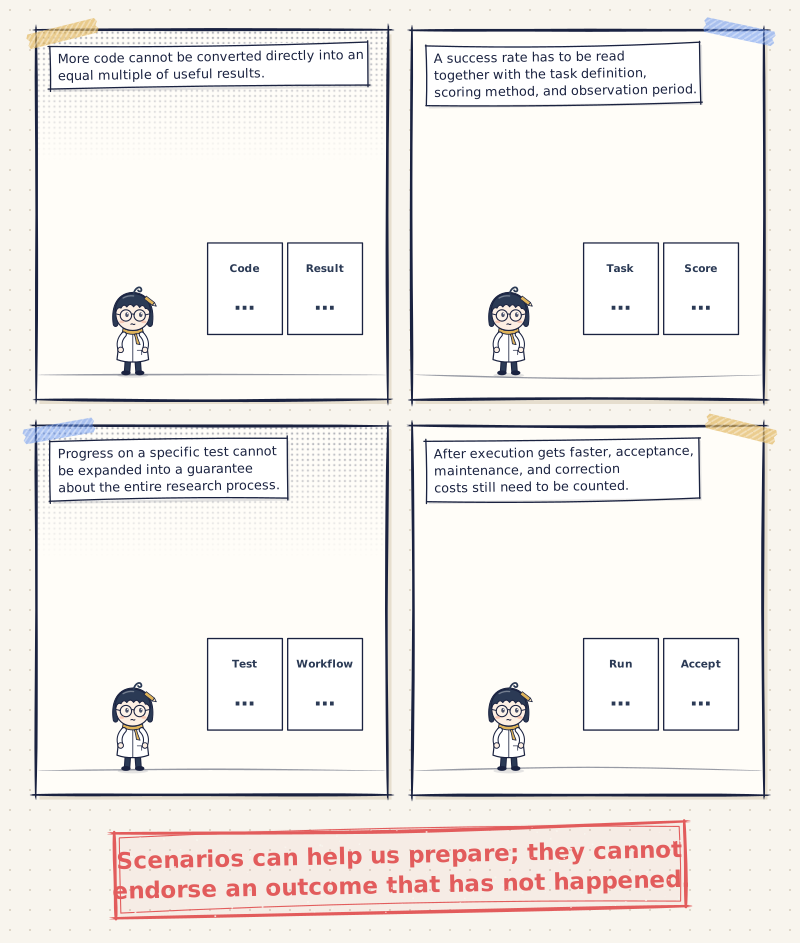
More code cannot be converted directly into an equal multiple of useful results.
For my own work, that warning is more useful than the multiple. A longer output may solve more problems, or it may create more work in reading, maintaining, and correcting it. Any claim about efficiency also needs to account for the purpose, quality, and subsequent work attached to the delivery.
Percentage: What Kind of Task Succeeded?
Another reported figure concerns the most open-ended category of Claude Code sessions. In May 2026, its success rate reached 76 percent, an increase of about fifty percentage points over six months. This was a company metric judged by Claude, and the composition of the tasks can affect the result. It should not be described as growth from single digits to 76 percent, nor as the success probability of every request.
A success rate has to be read together with the task definition, scoring method, and observation period.
For example, asking a tool to organize a document and asking it to diagnose an unexplained error call for different evidence. One aggregate percentage cannot decide the acceptance process for both kinds of work.
A Long Task Is More Than the Time on a Timer
The task-duration metric cited in the source concerns a particular task set and a particular success threshold. It does not mean that a model worked without interruption and with the same reliability for that length of time. Any projection into the future should also be treated as a conditional extrapolation.
For that reason, I do not want to ask only how many hours a tool can run. More useful questions are what it obtained during that time, which parts are reproducible, how failure is reported, and whether it leaves a result that another person can take over.
A task continuing to run and its result being worth adopting require separate confirmation.
If a tool runs for a long time but no one knows which version it changed, duration alone does not help me assess progress.
One Successful Experiment Still Raises the Question of Transfer
When I read about acceleration or improvement in an experiment, I next ask whether the starting conditions were comparable, which goals were specified by people in advance, what the scoring covered, and whether the result transfers to another scale or setting.
Those questions do not dismiss the experiment. They help determine which conclusion the experiment can support. Optimizing one specified piece of code and demonstrating the same acceleration across an actual training process clearly require different evidence.
Progress on a specific test cannot be expanded into a guarantee about the entire research process.
I no longer fill unverified intermediate values into a continuous curve or attach illustrative proportions to named models. A smaller number of clearly defined figures is more useful than a visually complete but unsupported trend.
More Output Requires More Acceptance Capacity
For me, the most practical question raised by this reading is who has time to confirm the results when a tool can produce many of them simultaneously.
I want every delivery to explain at least three things: why it was done, what actually changed, and which criteria were used to check it. Parts that did not pass should remain in the record rather than disappearing beneath a blanket statement that the task is complete.
After execution gets faster, acceptance, maintenance, and correction costs still need to be counted.
I do not turn this into a claim that people will stop writing code or that execution is already free. Tools, compute, human attention, and continuing responsibility can all affect whether an approach is worth adopting.
Future Scenarios Are for Preparation, Not Probability Reporting
The source discusses three broad directions: progress encounters limits; development keeps accelerating while people retain directional control; or systems reach full recursive self-improvement. These are scenarios used by the authors to consider consequences, not measured probabilities.
I bring them back to more concrete preparation. Which changed constraints would require a new assessment? Which work would still require permissions, verification, and assigned responsibility even if the tools became more capable? If an assumption proves false, how would the process stop or adjust?
Scenarios can help us prepare; they cannot endorse an outcome that has not happened.
What I Want to Preserve Is Responsibility for Direction
After reading this material, I still care deeply about what should be done. But I do not need to prove that AI can never exercise judgment in order to explain what I should remain responsible for.
In my work, someone has to own the value trade-offs, acceptable risks, authorization boundaries, and the consequences of the result ultimately adopted. A tool can propose options, locate information, or point out a blind spot. Those contributions do not automatically remove human responsibility.
That is a choice about how I work, not a ranking of human and machine essence derived from a test percentage.
Return to the Question Mark in the Unclosed Loop
What I want to keep asking after this article is not merely what the next multiple will be, but how far the claim stands from the evidence.
What does one number establish? Which observation is still missing? Who could challenge it? When the result falls short, can the process acknowledge and correct it? Those questions deserve to improve alongside model capability.
The value of judgment is practiced through concrete choices and their consequences.

💬 Comments
Loading...