Can strong results in an AI survey tell me how much work inside an office has actually changed?
Reading Microsoft’s 2025 Work Trend Index, I want to distinguish expectations, reported use, and how a particular task performs. They can inform one another without becoming interchangeable.
The earlier essay put numbers beside impressions from people around me and rushed to judge whether Taiwanese businesses were ready. I would now make the question smaller: whom did the report ask, what did it ask, and which part of my work might it help arrange?
1. Begin with the survey’s scope
The global report’s methodology describes a survey conducted from February 6 to March 24, 2025, among 31,000 full-time employed or self-employed knowledge workers across 31 markets, with 1,000 per market. It was not a census of every company and cannot directly represent every kind of work across Taiwan’s industries.
The report also uses other data and interviews. Survey answers, product usage signals, and case interviews nevertheless provide different evidence. Before reading a percentage as a conclusion, I need its source and population.
This is a look back at a 2025 survey, rather than a live ranking of Taiwan’s AI readiness in 2026. A Taiwanese percentage above the global average does not establish first place in every capability.
2. Expectations and use both need their questions
According to Microsoft’s Taiwan release of April 25, 2025, 88% of Taiwanese business leaders considered 2025 a pivotal year to rethink core strategy and operations, compared with 82% globally. That describes surveyed leaders’ view of the moment, not 88% of companies having completed a transformation.
The same release says 58% of companies were using agents to fully automate work in departments or teams, or business processes, compared with 46% globally. This concerns respondents’ reported use and cannot all be dismissed as awareness alone. The release does not thereby verify each reported workflow’s quality, cost savings, or sustained operation.
Having heard of agents, planning adoption, reporting current use, and having checkable outcomes can be different questions. Keeping those distinctions helps more than calling every positive number either success or empty talk.
3. A company category is not a success certificate
The report uses “Frontier Firm” for early adopters meeting its specified conditions. The category includes reported AI deployment, investment, use, and future arrangements, rather than an independent outcomes certification for each company.
I would therefore not treat differences in that group’s self-assessments as proof that adopting agents makes a company thrive. Selection criteria, work types, and other differences need consideration too.
Microsoft’s ideas about on-demand intelligence, human–agent collaboration, and reorganizing work can offer directions for discussion. I still want room for expertise, regular coordination, and human judgment, rather than treating all of them as obsolete habits.
4. Keep personal impressions within the questions they can answer
Managers and workflows someone encounters can suggest further questions without estimating how many Taiwanese companies have transformed. The earlier essay supplied no checkable work records, so I no longer use one person’s output equaling five to eight people’s work as evidence of adoption benefits.
Consider a hypothetical document-organizing task: an agent classifies material and lists uncertainties for a person to check. Recording only “adopted” still leaves us unaware of misclassifications, time spent fixing them, and whether the next person can use the result.
I would rather see records of the same task under clear conditions. A trial might deserve more time, a narrower scope, or a pause. Those choices should depend on actual burdens and quality, rather than treating broad rollout as a test of a team’s progressiveness.
5. Four questions about one task
After reading an adoption report, I would choose a task and ask:
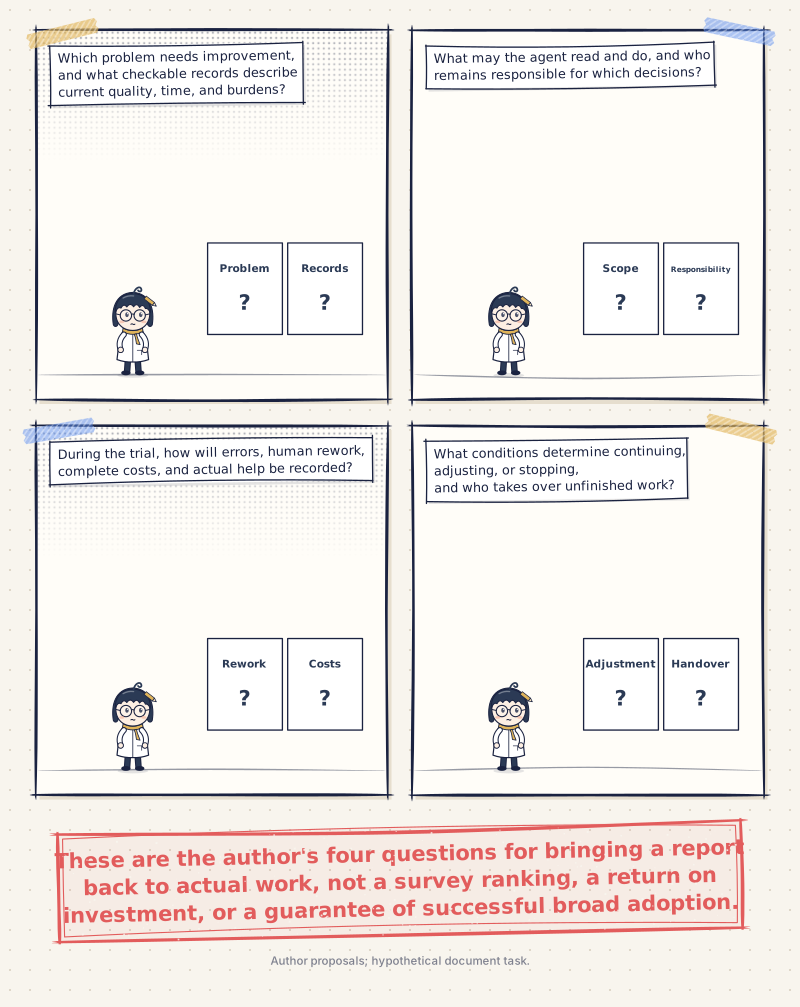
- Which problem needs improvement, and what checkable records describe current quality, time, and burdens?
- What may the agent read and do, and who remains responsible for which decisions?
- During the trial, how will errors, human rework, complete costs, and actual help be recorded?
- What conditions determine continuing, adjusting, or stopping, and who takes over unfinished work?
These are the author’s four questions for bringing a report back to actual work, not a survey ranking, a return on investment, or a guarantee of successful broad adoption.
Costs, permissions, and handovers in continuous AI service asks a related question: a service appearing always available does not mean responsibilities and exceptions have all been handled. A trial needs results people can question before the discussion can continue.
6. Let numbers support questions, rather than stand in for work
I still care about how AI might change work and want reports to help me understand other people’s directions. Survey expectations need not become an inevitable future in my writing, and frustrations around me cannot erase the use respondents have reported.
For a team, explaining the problem being addressed, uncertain results, and who will take over is more useful than proving it fits a company label.
The next time I see a percentage described as readiness, I want to ask: ready for which task, and what records will let other people see how it performs?
Materials and verification limits — revised November 4, 2026
Microsoft’s 2025 Taiwan release and the global report’s methodology, categories, and relevant published questions were checked directly. Raw survey data and a complete questionnaire were not obtained, Taiwanese percentages were not recalculated, and particular companies were not verified. Comparisons of thriving and meaningful work differ in numbers, populations, or regions between the global page and Taiwan release; they are not combined or silently replaced. This is not a 2026 ranking, causal study, or cost estimate. Document organization is explicitly hypothetical, and the four questions are author proposals. The original publication date is retained.
Revision note: Removed claims that Taiwan leads every indicator globally, that all numbers measure awareness alone, that one person substitutes for five to eight, and blanket accounts of Taiwanese companies’ culture or trials. Category differences in self-assessment no longer prove adoption outcomes. Sources, populations, questions, and work records are examined separately.

💬 Comments
Loading...