Once AI has ranked several market opportunities, is the highest-scoring one necessarily the direction a company should take?
It may deserve investigation. But we still need to know how the score was produced, what it leaves out, and who is authorized to accept the costs.
My concern about algorithm worship remains. What deserves criticism is treating an unverified recommendation as a guarantee of success and shifting the consequences to the tool—not denying that AI can assist judgment or treating human intuition as superior evidence.
TL;DR: Organizing data, predicting, optimizing, and authorizing adoption are different activities, but need not be described as an unbridgeable gulf. Structured, semi-structured, and unstructured describe how data is organized, not levels of computability. AI may improve a question, misunderstand it, or overlook something; it cannot guarantee the best answer. I retain my reflection on finitude and responsibility, while using four checks—objectives, evidence, omissions, and authority—to support bounded decision assistance.
1. Identify the kind of help the tool is providing
Tabulating market information, estimating an outcome, comparing options against an objective, and approving resources are different activities. One system may participate in several, but success in earlier steps does not automatically authorize later adoption.
Suppose a model ranks market A first. Is it organizing existing information or predicting the future? Is the score based on revenue, risk, team capabilities, or a combination of weighted factors? This is an illustration, not a new record of an actual company decision.
When objectives and constraints are explicit, optimization can form part of a decision. Conditional options can also be compared under uncertainty. The question is whether the conditions fit the work, not whether all decisions are inherently beyond computation.
I do not want criticism of overpromising to dismiss useful analysis along with it.
2. Data formats are not a ladder from computable to uncomputable
Structured data can be organized in fixed fields; unstructured content lacks the same fixed tabular form. Semi-structured data retains some organization. These categories describe arrangement, not trustworthiness or a ranking of how far understanding can go.
An email may have sender and date fields alongside free text. Market reports and meeting transcripts cannot all be called semi-structured. Recording a person’s glance does not make it inherently beyond all possible analysis, either.
AI can process more than tables. For example, the 2025 Gemini 2.5 developer report describes capabilities involving text, images, audio, and long content.[1] This is historical material countering the “tables only” claim, not a guarantee of correctly understanding every contract, conversation, or situation.
What needs inspection is the content, task, and result—not a declaration that a tool must understand or cannot understand something based on a data category alone.
3. Intuition can suggest a lead, not validate itself
An analysis may omit an important condition, and intuition may prompt us to investigate. Intuition can also be affected by preferences, memory, or position. Being hard to quantify does not automatically make it more reliable than a model.
The original used a remark over dinner to illustrate a leap in judgment. This revision neither reconstructs it as a traceable personal conversation nor concludes that algorithms can never observe or model any of the information involved.
I would turn intuition into questions we can discuss: is a market constraint missing? Is the information reliable? If it is false, would we still make the same choice?
These are my working suggestions, not an experiment establishing intuition’s superiority. Choosing A or B requires reasons; deliberately doing the opposite of AI is no guarantee of a unique competitive advantage.
4. Responsibility can rest on procedures, not one person’s solitary leap
I use “the cult of science” to describe excessive expectations of guaranteed certainty. It is my critical rhetoric, not a definition of every religion or a psychological diagnosis that everyone using decision tools is avoiding pain.
What troubles me is a team adopting a model score without asking who set the objective, who accepts the risks, or who can pause the process when information is insufficient.
NIST’s 2023 AI risk framework calls for clarifying human–AI roles and organizational leadership’s responsibility for risk. The OECD AI Principles likewise discuss accountability and traceability by role and context.[2][3] These directions neither prohibit automation nor require one person to recalculate every decision.
Depending on the work, teams, professional procedures, or bounded automation can execute decisions. Whatever arrangement is adopted must explain authorization limits, error handling, and responsible people. “AI told me to” is insufficient. This essay is not a legal analysis for a particular industry.
5. Finitude reminds me to acknowledge uncertainty, not stop checking
Finitude in my theological training offers one perspective: knowledge and vision have boundaries, and we still try to act responsibly within them. This is my faith reflection, not mathematical proof that decisions are uncomputable.
Accepting limits does not make data unimportant or tools unhelpful. It reminds me that a score does not automatically contain all relevant context, and a plausible explanation does not remove the need for further checks.
AI may sometimes flag a faulty premise or continue reasoning from one. “Output quality can never exceed question quality” and “it always faithfully answers only what was asked” cannot be universal laws. Domain knowledge and verification remain necessary.
The original marks these thoughts as originating in 2017 and being revisited in 2026. This revision retains that background without access to the original 2017 version, and adds no private remarks, team cases, or numerical outcomes from that period.
6. Turn advice into accountable adoption
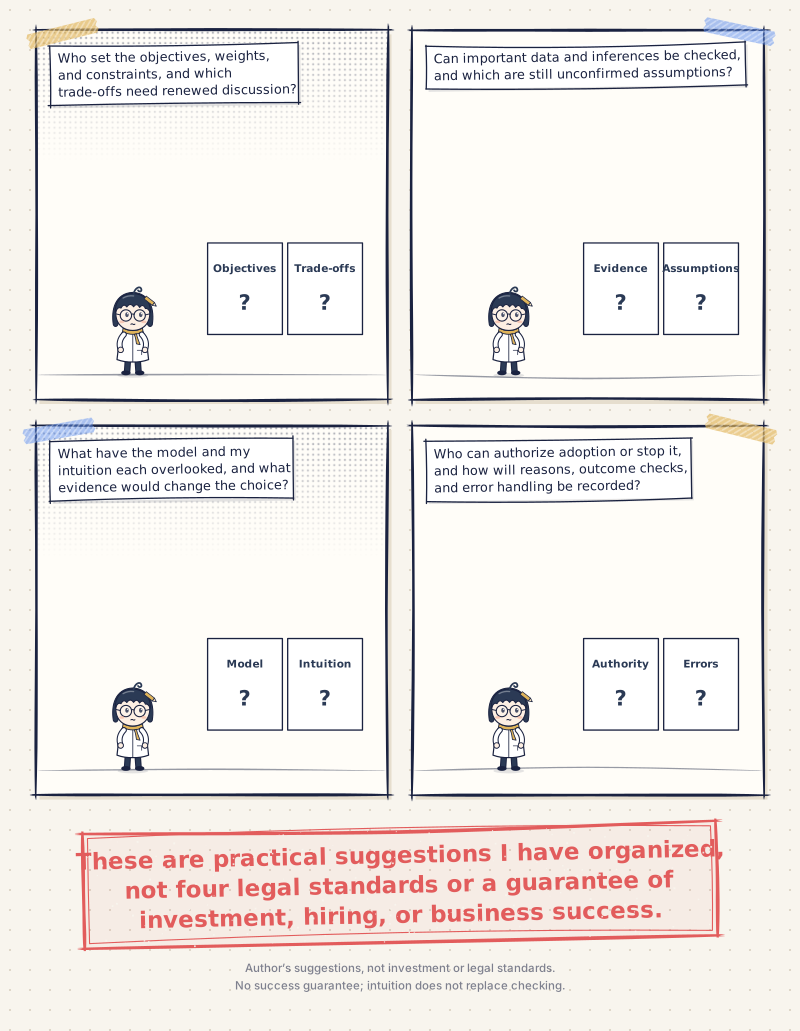
The next time I receive AI analysis, I would ask four questions:
- Who set the objectives, weights, and constraints, and which trade-offs need renewed discussion?
- Can important data and inferences be checked, and which are still unconfirmed assumptions?
- What have the model and my intuition each overlooked, and what evidence would change the choice?
- Who can authorize adoption or stop it, and how will reasons, outcome checks, and error handling be recorded?
These are practical suggestions I have organized, not four legal standards or a guarantee of investment, hiring, or business success.
If a tool claims to improve decisions, I am willing to examine its tests, scope, and failures. I object to unsupported promises of certain success, not every product that assists judgment.
Tools can reveal more options. After using them, an organization should still explain why it adopted a recommendation, which costs it accepted, and who will see the problem through when events depart from expectations.
Sources and reading limits (checked through November 4, 2026)
- Gemini 2.5 technical report v1, July 7, 2025, passages on the model and multimodal capabilities. A developer report used only as a historical example beyond tables, not a 2026 ranking or endorsement of an individual analysis.
- NIST, AI Risk Management Framework 1.0, January 2023, GOVERN 2.3/3.2 and MAP 1. Used for directions on risk responsibility, roles, and context, not a law prohibiting automation or a completed evaluation of an individual deployment.
- OECD, official AI Principles page, Accountability in the principles revised in 2024. Discusses responsibility, traceability, and risk management according to roles, context, and ability to act; it does not give these four questions legal force.
Revision note: This version corrects data categories and the claim that AI handles only tables. It withdraws assertions that intuition necessarily wins, algorithms can never judge, or all decision-assistance platforms are untrustworthy. The critique of certainty worship remains, without inferring the psychology of all religions or tool users.

💬 Comments
Loading...