As AI starts splitting work and assigning subagents, what judgments still need to be made? I want to focus on something practical: someone must define the task, its permitted scope, and the evidence that will count as completion.
Automatic coordination makes boundaries more visible
Give a tool a large task and it may outline a plan, then handle several questions separately. That is appealing: I need not design every step from scratch, and I may get different answers to compare.
Yet a division of labor is not evidence of reliable results. A detailed plan can misread the requirement; several answers can share one mistaken premise. What I want to know is which question the arrangement helps answer with checkable evidence.
Separate orchestration settings from reasoning effort
For Claude Code, the official model configuration documentation, consulted on November 4, 2026, distinguishes the Ultracode orchestration setting from model effort levels. From v2.1.284 onward, toggling the setting does not automatically change effort; starting with --effort ultracode also sets xhigh. Earlier versions behave differently, so one screen cannot establish a rule for every version. Nor is xhigh the deepest documented level: max is also listed.
These distinctions clarify terminology rather than recommend a setting. This revision did not rerun features, compare models, or verify my previous operating records. Current documentation cannot substitute for release records from the period concerned.
The official workflow documentation describes scripts that coordinate subagents. Tool permission checks still apply, and runs have concurrency and total-agent limits. Automatic orchestration therefore does not mean unlimited resources, every permission, or checking until no vulnerability remains.
Different roles should bring different checks
Suppose a change can be split into requirements review, implementation, and verification. Separate work may help. Whether it can be separated depends on shared-file contention, decisions that are not yet settled, and who integrates the results. Sequential dependencies still need their sequence.
I want a checker to know which assumption to challenge and which materials they actually read. Being asked to argue against a result does not ensure that a problem will be found. Finding none is not proof that there are no flaws.
This article no longer uses one version-management experience or large migration figures without primary records to estimate the efficiency of all multi-agent work. A polished table cannot fill gaps in task size, test coverage, or the definition of completion.
Put resources and stopping conditions in the plan
Splitting work may save time, but it can also add repeated reading, retries, and integration. I want to know which uncertainty deserves more resources and what conditions will end the run.
For example, a small number of roles could first answer independent questions, then check whether their sources overlap before deciding on another round. If essential material remains missing, more text may not improve the answer. At a budget, time, or permission boundary, record the results and unknowns so a successor understands why work stopped.
This is my suggested arrangement, not a claim that a product already supplies every budget control, or a formula connecting agent count to quality.
Four questions I would ask first
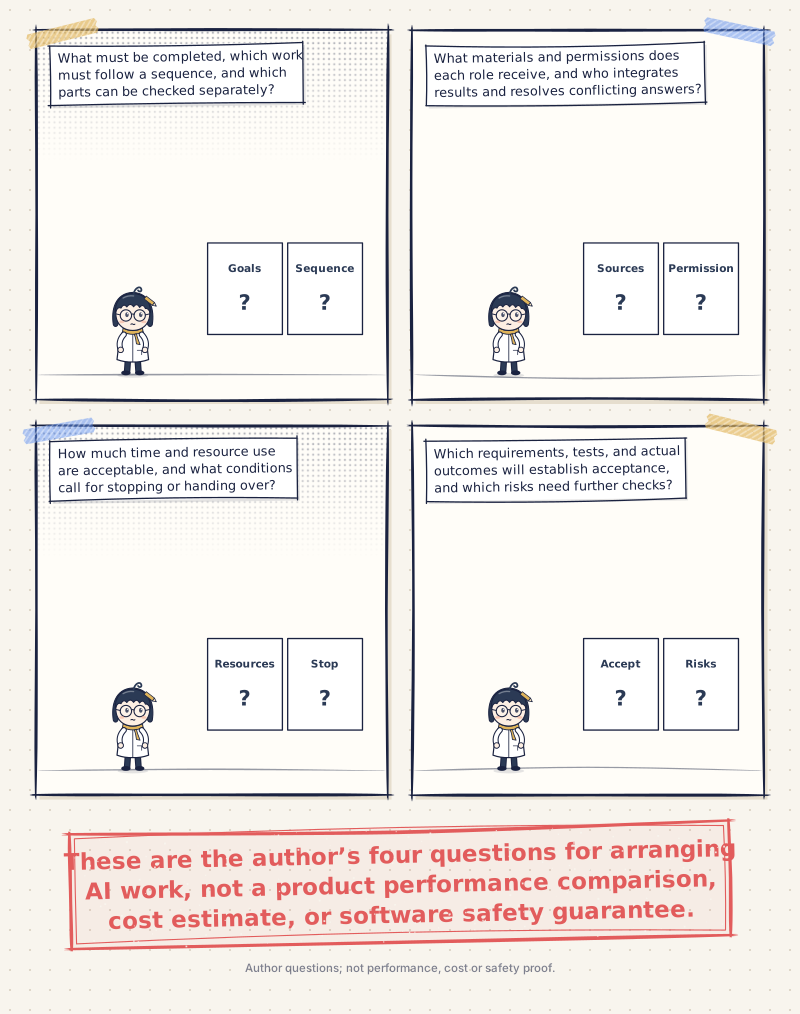
- What must be completed, which work must follow a sequence, and which parts can be checked separately?
- What materials and permissions does each role receive, and who integrates results and resolves conflicting answers?
- How much time and resource use are acceptable, and what conditions call for stopping or handing over?
- Which requirements, tests, and actual outcomes will establish acceptance, and which risks need further checks?
These are the author’s four questions for arranging AI work, not a product performance comparison, cost estimate, or software safety guarantee.
Tools can help judgment; someone must own the outcome
I still value judgment and taste. But acceptance involves more than whether something looks good. Whether requirements are met, what tests cover, whether performance fits the situation, and whether an external action actually completed each need their own evidence.
Tools can organize options, find counterexamples, and help design checks. People can accept a better judgment suggested by a tool; there is no need to declare judgment forever beyond automation. What needs to be clear is who can decide, who confirms the result, and which conclusions remain unavailable.
I hope automatic coordination saves some effort in arranging work. I am willing to spend that effort checking: is this worth doing, and how far has this result actually been completed?
Materials and verification scope: Revised November 4, 2026. Only the two current official Claude Code documents above were used to check necessary setting and workflow concepts. Features were not retested, older personal operations were not verified, and primary Bun migration records were not obtained. Earlier precise scale, timing, pass-rate, and release-history claims are omitted. The remaining discussion is the author’s reflection on working methods, not a model ranking or purchasing recommendation.

💬 Comments
Loading...