TL;DR: Felix Rieseberg’s tutorial on AI ambition already explains that models need a computer where software can be installed and relevant data accessed, and he specifically insists on external validation. This article draws on my experience using three AI systems to audit Claude, adding what he left unexplored: how to build external validation when using a different vendor’s model as reviewer, and why that setup changes the scope of work you’re willing to delegate.
Felix Rieseberg is an engineering manager at Anthropic who has led engineering on Claude.ai, Cowork, and the desktop version of Claude Code. On October 13, he published “How to be more ambitious: A tutorial for humans with models” on his personal site, sharing a shift in his own practice: he used to ask Claude to fix one crash at a time, then simply asked Claude to keep the team’s apps crash-free.
To make that work, he gave Claude access to crash reports, a mapping between versions and code, and three operating systems so it could reproduce issues itself and verify fixes.
Why Is “Be More Ambitious with AI” So Hard to Act On?
Felix says that people working in AI, himself included, often repeat “be more ambitious” as a slogan, reposting impressive results with a note that people still aren’t thinking big enough. He also acknowledges how hard that advice is to follow, which is why he breaks ambition into four kinds:
| Ambition | Meaning | Felix’s Example |
|---|---|---|
| Speed | Do the same work in less time | Writing code with Claude is faster. He considers this well-established and skips it. |
| Altitude | Raise the level of delegation, from individual tasks to the outcome you actually want | He stopped asking Claude to fix one crash at a time and delegated the outcome: keep the team’s apps crash-free. |
| Depth | Work like a top specialist: engage raw data, professional tools, and root causes directly | Insist on tools like databases and statistical models that experts actually use; give it raw data and ask it to pressure-test your assumptions; use outside judges and never let the model evaluate itself. |
| Range | Bring in fields beyond the one the task seems to need, using knowledge, tools, and techniques you wouldn’t normally use | Turn nouns into verbs to find applicable fields; assemble a cross-disciplinary team for the task. |
For each of the last three, he lists specific approaches, with sample prompts for some.
He closes with a section on self-efficacy in psychology, on how people are constrained by what they believe is possible. Before that, he states the prerequisites clearly: the approaches he describes all require the model to have a computer where software can be installed and relevant data accessed. His prompting framework for going deeper also contains three items that map directly onto data, tools, and external validation: what is the most primary material available, what methods and tools should be used, and what, beyond you and the model, can confirm the result is correct.
The computer and the data are prerequisites he names explicitly. External validation is one technique within the depth section, and he specifically insists on it. He also observes that stronger models seem better able to take on higher-level goals directly, though he notes that in 2026 simply telling Claude to go make money probably still doesn’t work for most companies. Going by his article, part of AI ambition rests on infrastructure. The no-more-crashes example is itself a verification pipeline. I want to add what he didn’t expand on: how to set up external validation when using another vendor’s model as reviewer, and why that setup changes what you’re willing to delegate.
How Do You Set Up an Outside Judge for AI?
Felix’s treatment of outside judges in the depth section is only a few lines: “Do not ask the model to judge itself.” He recommends external validation through tools the model can run and get immediate feedback from. He assumes this will eventually be solved as models get smarter, but in October 2026, he implores readers to insist on external validation. Huang et al.’s 2023 study, testing models including GPT-3.5 and GPT-4, found that without external feedback, models struggle to self-correct their reasoning, and sometimes do worse after trying.
Over the past several months, I’ve added another form of external validation: having a model from a different vendor do the reviewing. It doesn’t provide the immediate feedback that an executable tool does, and its independence is limited. More on that shortly. When I wrote my U.S.-Iran war analysis in July, I had Grok retrieve data and compile a report, passed that to Perplexity for restructuring, and then asked Claude to write the draft. A separate agent handled fact-checking: given only the finished output, it was told to open every link. It compared a Bruegel PDF and an OFAC notice against the draft and flagged three hard errors. Looking back, all three models made errors during their reporting or drafting stages. At least in that test, retrieval quality was better than I expected.
My current setup looks like this:
| Role | Who Fills It | Safeguard |
|---|---|---|
| Executor | Claude Code | Output sent to three reviewers for error-checking |
| Reviewer | OpenAI’s Codex | Read-only; logs checked each time to confirm which model actually ran |
| Reviewer | xAI’s Grok | Three-layer read-only: tool list, permission rules, sandbox |
| Reviewer | Google’s Antigravity | Read-only; restricted to Google’s own Gemini |
| Researcher | Perplexity | Retrieves data with original sources attached for later verification |
| Decision-maker | Me | Important facts traced back to original sources |
This division of labor gets adjusted with each model generation. I covered four kinds of false assurance I saw in this round in “The Most Dangerous Thing About an AI Review Report Is That It Looks Like Something Was Checked”. Here I’ll focus on two setup lessons.
When I first configured Grok on my Mac, I restricted it from writing files. After being blocked, it switched to shell and tried to write through a different path, until the macOS sandbox finally stopped it. After that, I added three layers of read-only constraint for Grok: a tool list that only exposes read operations, permission rules that block writes and command-line access, and a sandbox as the last line. If one layer is bypassed, the next one holds.
Codex gave me the habit of checking logs. Once a misconfiguration went undetected: no error was thrown, it silently fell back to the default model, and the resulting report looked just as thorough. Since then I always go back to the logs to confirm which model actually ran.
Why Isn’t Having Multiple AIs Cross-Check Each Other Enough?
There are at least two dimensions to reviewer independence. The first is not being swayed by whoever produced the work: the question given to the reviewer must not carry my conclusions embedded in it. I wrote about the mechanics of that in I Had Codex Catch Claude’s Mistakes. But I Don’t Just Take Its Word for It. In the July fact-check, I also established a rule that the reviewer couldn’t read the original producer’s reasoning first, to avoid being led by the same argument. The second dimension is lineage: which company made the model and what architecture it uses. When I use Antigravity for a second opinion, I restrict it to Google’s own Gemini even though Claude is on its model list, so it doesn’t turn into Claude reviewing Claude.
Even with both layers, independence remains limited. Kim et al.’s 2025 study analyzed responses from over 350 models across two leaderboard benchmarks. On one benchmark, when two models both answered incorrectly, they gave the same wrong answer about sixty percent of the time. Same-company models correlated more strongly, which makes switching vendors reasonable; but larger, more accurate models showed high error correlation even across companies and architectures, so changing vendors alone isn’t sufficient.
That study measures benchmark performance; the paper also notes that this correlation affects outcomes when models are used as evaluators. My extension: when models cross-check each other, they may miss the same mistakes together. The reason the July fact-check caught errors was that the reviewer actually opened the Bruegel PDF and the OFAC notice. Returning to original sources, or verifying with executable tools, is what makes these shared errors more likely to surface. That aligns with what Felix says about preferring tools over model-as-judge.
Where Does Self-Efficacy Come From?
Felix closes with self-efficacy, noting that evidence exists for deliberately cultivating it. He cites Locke and Latham’s retrospective on 35 years of goal-setting research: people given specific, difficult goals consistently outperform people told simply to do their best.
In the same paper, Locke and Latham write that for goals to work, people need feedback that shows how far they are from the target. Without knowing how they’re doing, adjusting effort and approach becomes difficult, sometimes impossible.
In the context of human-AI collaboration, I think the mechanisms that catch errors can be seen as this kind of feedback. Felix was able to delegate the outcome of keeping the apps crash-free to Claude because reproduction and verification were already wired in. I can now let three AIs review Claude’s output with confidence because past failures led me to add read-only constraints and log-checking, and because I trace important facts back to original sources. The more reliable the error-catching mechanisms, the more willing people are to hand bigger work to AI.
This connects to what I wrote in March in Knowledge Management Runs on Pipelines, Not Discipline. But doing the July fact-check showed me that conclusion was only half right: a pipeline can move information and preserve sources, but someone still has to decide to run it. The same is true of ambition. No matter how solid your error-catching infrastructure, the final call belongs to a person. The super individual I often talk about is one person producing team-scale output. My February piece focused on orchestration and judgment; looking back now, I’d add these layers of error-catching mechanisms.
Wings Strapped to the Wrists
Felix opens his article with a flight metaphor for the gap in how people use AI. His cover image is a flight print, “Modo de volar” (A Way of Flying), from Goya’s late Disparates (Follies) series: five figures wearing bird-headed helmets with wings strapped to their wrists and ankles. The Metropolitan Museum’s notes mention the image has been read as a metaphor for the new political and philosophical currents that Spanish conservatives of the era opposed; it also calls to mind the hot-air balloon performances that were fashionable in Madrid at the time.
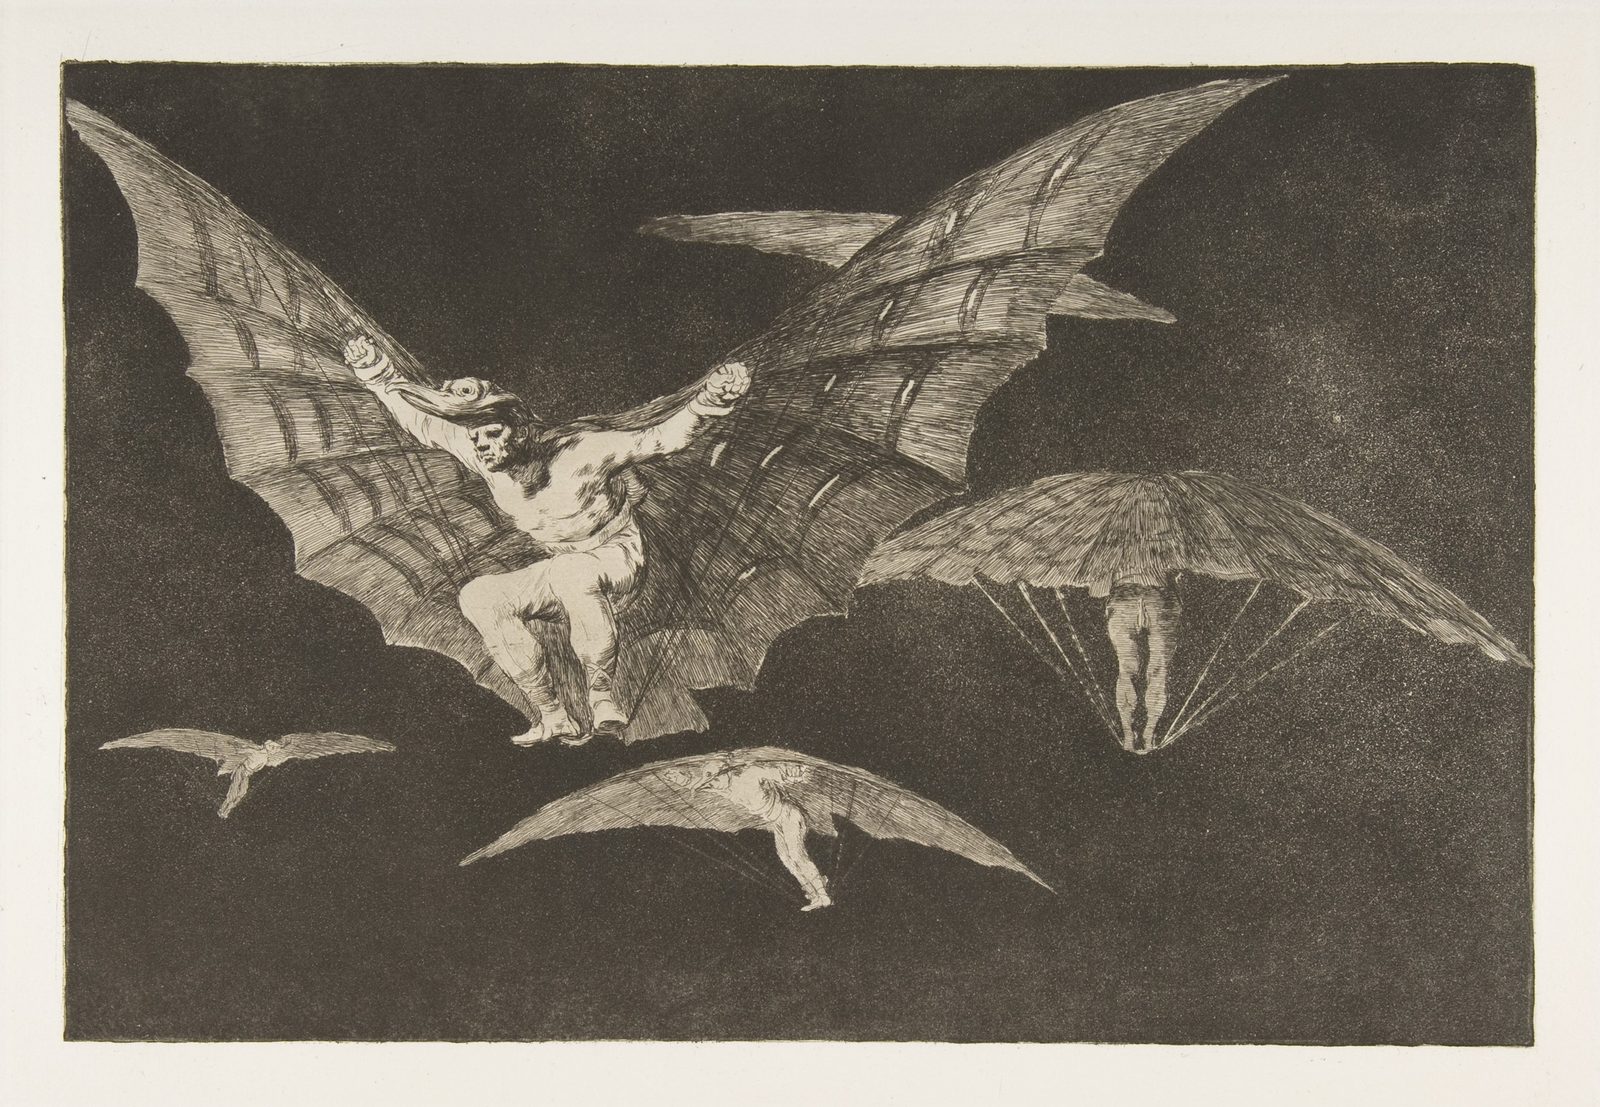 Goya, “Modo de volar” (A Way of Flying), c. 1815–16, published 1864. Image: The Metropolitan Museum of Art, public domain.
Whether Goya was hopeful about these figures or mocking them, I can’t say. What I notice is that between the wings and the body, there are still a few straps that have to be fastened by hand.
It’s the same with AI. Once I’ve handed the work over, I still need to know where to check when something goes wrong, how to pull it back when it drifts, and who bears the final decision. Each time these become a little clearer, I dare to push work I once wouldn’t have delegated a little further.
So if you hope to use AI more ambitiously, first check whether the straps that let you verify, correct, and take responsibility are fastened. Real courage grows in these details. Only when you know how you’ll respond to possible mistakes do you have room to think about where else you can fly.
You can also browse the full series from the Intelligence & Order topic page.
💬 Comments
Loading...